Gong Reviews 2026: What Verified G2 and TrustRadius Users Say About Pricing, Credits, Trackers and Support
Written by
Ishan Chhabra
Last Updated :
September 9, 2026
Skim in :
13
mins
In this article
Revenue teams love Oliv
Here’s why:
All your deal data unified (from 30+ tools and tabs).
Insights are delivered to you directly, no digging.
AI agents automate tasks for you.
Thank you! Your submission has been received!
Oops! Something went wrong while submitting the form.
Meet Oliv’s AI Agents
Hi! I’m, Deal Driver
I track deals, flag risks, send weekly pipeline updates and give sales managers full visibility into deal progress
Hi! I’m, CRM Manager
I maintain CRM hygiene by updating core, custom and qualification fields all without your team lifting a finger
Hi! I’m, Forecaster
I build accurate forecasts based on real deal movement and tell you which deals to pull in to hit your number
Hi! I’m, Coach
I believe performance fuels revenue. I spot skill gaps, score calls and build coaching plans to help every rep level up
Hi! I’m, Prospector
I dig into target accounts to surface the right contacts, tailor and time outreach so you always strike when it counts
Hi! I’m, Pipeline tracker
I call reps to get deal updates, and deliver a real-time, CRM-synced roll-up view of deal progress
Hi! I’m, Analyst
I answer complex pipeline questions, uncover deal patterns, and build reports that guide strategic decisions
TL;DR
Gong holds 4.7 on G2 across roughly 6,694 reviews, 9.1 on TrustRadius, 4.8 on Capterra, and 4.7 on Gartner Peer Insights. Quality is not the issue.
Recurring complaints cluster on scope, cost per outcome, and rollout effort. Accuracy and transcription quality are rarely the objection reviewers raise.
Gong credits meter question-based AI trackers, AI Ask Anything, AI Briefer, and the MCP server. Caps do not roll over, and the API errors at zero.
Gong Foundation advertises unlimited AI trackers while credit documentation names them the biggest consumer. Unlimited to create is not unlimited to run.
TrustRadius scores support near 8.6 but implementation near 5.7. The helpdesk answers; the configuration work lands on your internal owner.
Cost complaints split three ways: seat price, separately licensed modules, and licences bought for people who never log in. Audit dormant seats first.
Q1. What do Gong reviews actually say in 2026? [toc=1. The 2026 Verdict]
Gong reviews in 2026 are strongly positive. Gong holds 4.7 out of 5 across roughly 6,694 G2 reviews, 9.1 out of 10 on TrustRadius across more than 1,000 ratings, 4.8 on Capterra, and 4.7 across verified Gartner Peer Insights reviews. Gartner also named Gong a Leader in its 2025 Magic Quadrant for Revenue Action Orchestration. The recurring criticisms are not about accuracy or reliability. They cluster on scope, cost per outcome, and rollout effort. Read them as feedback from people who broadly like the product.
📊 How this review set was read
Most Gong review round-ups never tell you how the quotes were picked. So here is the method first, before any finding.
Four platforms were read: G2, TrustRadius, Capterra, and Gartner Peer Insights. Only reviews that resolve to an individual review URL with a visible date were kept in the analysed subset. Product pages and unlinked quotes were excluded. The population rating is reported separately from that subset, and the two are never mixed.
That distinction matters more than it sounds. A platform average describes thousands of users. A quote describes one person on one day. The same discipline applies when you compare any revenue intelligence platform on peer-review evidence alone.
⭐ The ratings, reconciled in one place
Gong Ratings Across Four Review Platforms (2026)
Platform
Score
Volume
What it tells you
G2
4.7 / 5
~6,694 reviews
Broadest sample, heaviest on mid-market sellers
TrustRadius
9.1 / 10
1,090+ ratings
Deeper written detail, feature-level scoring
Capterra
4.8 / 5
561 reviews
Skews smaller companies
Gartner Peer Insights
4.7 / 5
~371 reviews
Identity-verified, enterprise-weighted
The four platforms agree. That agreement is the finding. When a product scores this consistently across different sampling methods, the quality question is answered, and the remaining questions are about fit and cost.
One number inside TrustRadius is worth pulling out early. Reviewers score Gong's support in the 8.2 to 8.6 range, but its implementation closer to 5.7. The helpdesk is not the weak point. The rollout is, which is why the Gong implementation timeline matters more than most buyers expect.
⚠️ What a single review can and cannot prove
A review proves that one person had one experience, on one date, on one module. Nothing more. It cannot establish how common something is, and it cannot tell you what a vendor charges.
That rule is why this article dates every quote in the body text. Review sites stack five years of releases on one page, so a 2024 complaint about a module Gong has since rebuilt sits beside a 2026 one and looks identical. Reading the current Gong feature set beside an older review is the only way to tell them apart.
"Design is user friendly and ensure the elements are visible and with no confusion... Real Time integrations can be time consuming." — Verified reviewer, "User-Friendly Design, but Real-Time Integrations Take Too Long" Gong G2 Verified Review [21 Apr 2026]
Those two sit at opposite ends of the same story. The product works. The question is how much of it you are actually going to use.
Q2. Why does a 4.7 rating make the complaints more useful, not less? [toc=2. How to Read the Reviews]
When a product averages 4.7, the criticisms that still recur are the ones people who like the tool cannot ignore. That makes them structural, not incidental. The limitation is real and worth stating plainly: buyers who evaluated Gong and chose something else never wrote a review, so the corpus describes users, not the market. Treat every theme as a hypothesis, date it, then check it against Gong's current documentation before you act on it at renewal.
🧾 The scene most readers are actually in
You have a renewal quote open in one tab and six thousand reviews in another. You are not deciding whether conversation intelligence is useful. You decided that two years ago.
You are deciding whether this specific bill is justified, and whether the complaints you are reading are about the product or about the price. Those are different problems with different answers, and the split between revenue intelligence and conversation intelligence is usually where it starts.
❌ Why the normal way of reading reviews fails
The default move is to sort by lowest rating and read the angry ones. It feels efficient. It is close to useless.
Review platforms present a five-year archive as if it were a snapshot. A complaint about a module that shipped in 2023 renders exactly like one written last month. Nothing on the page tells you which criticisms have survived two years of releases.
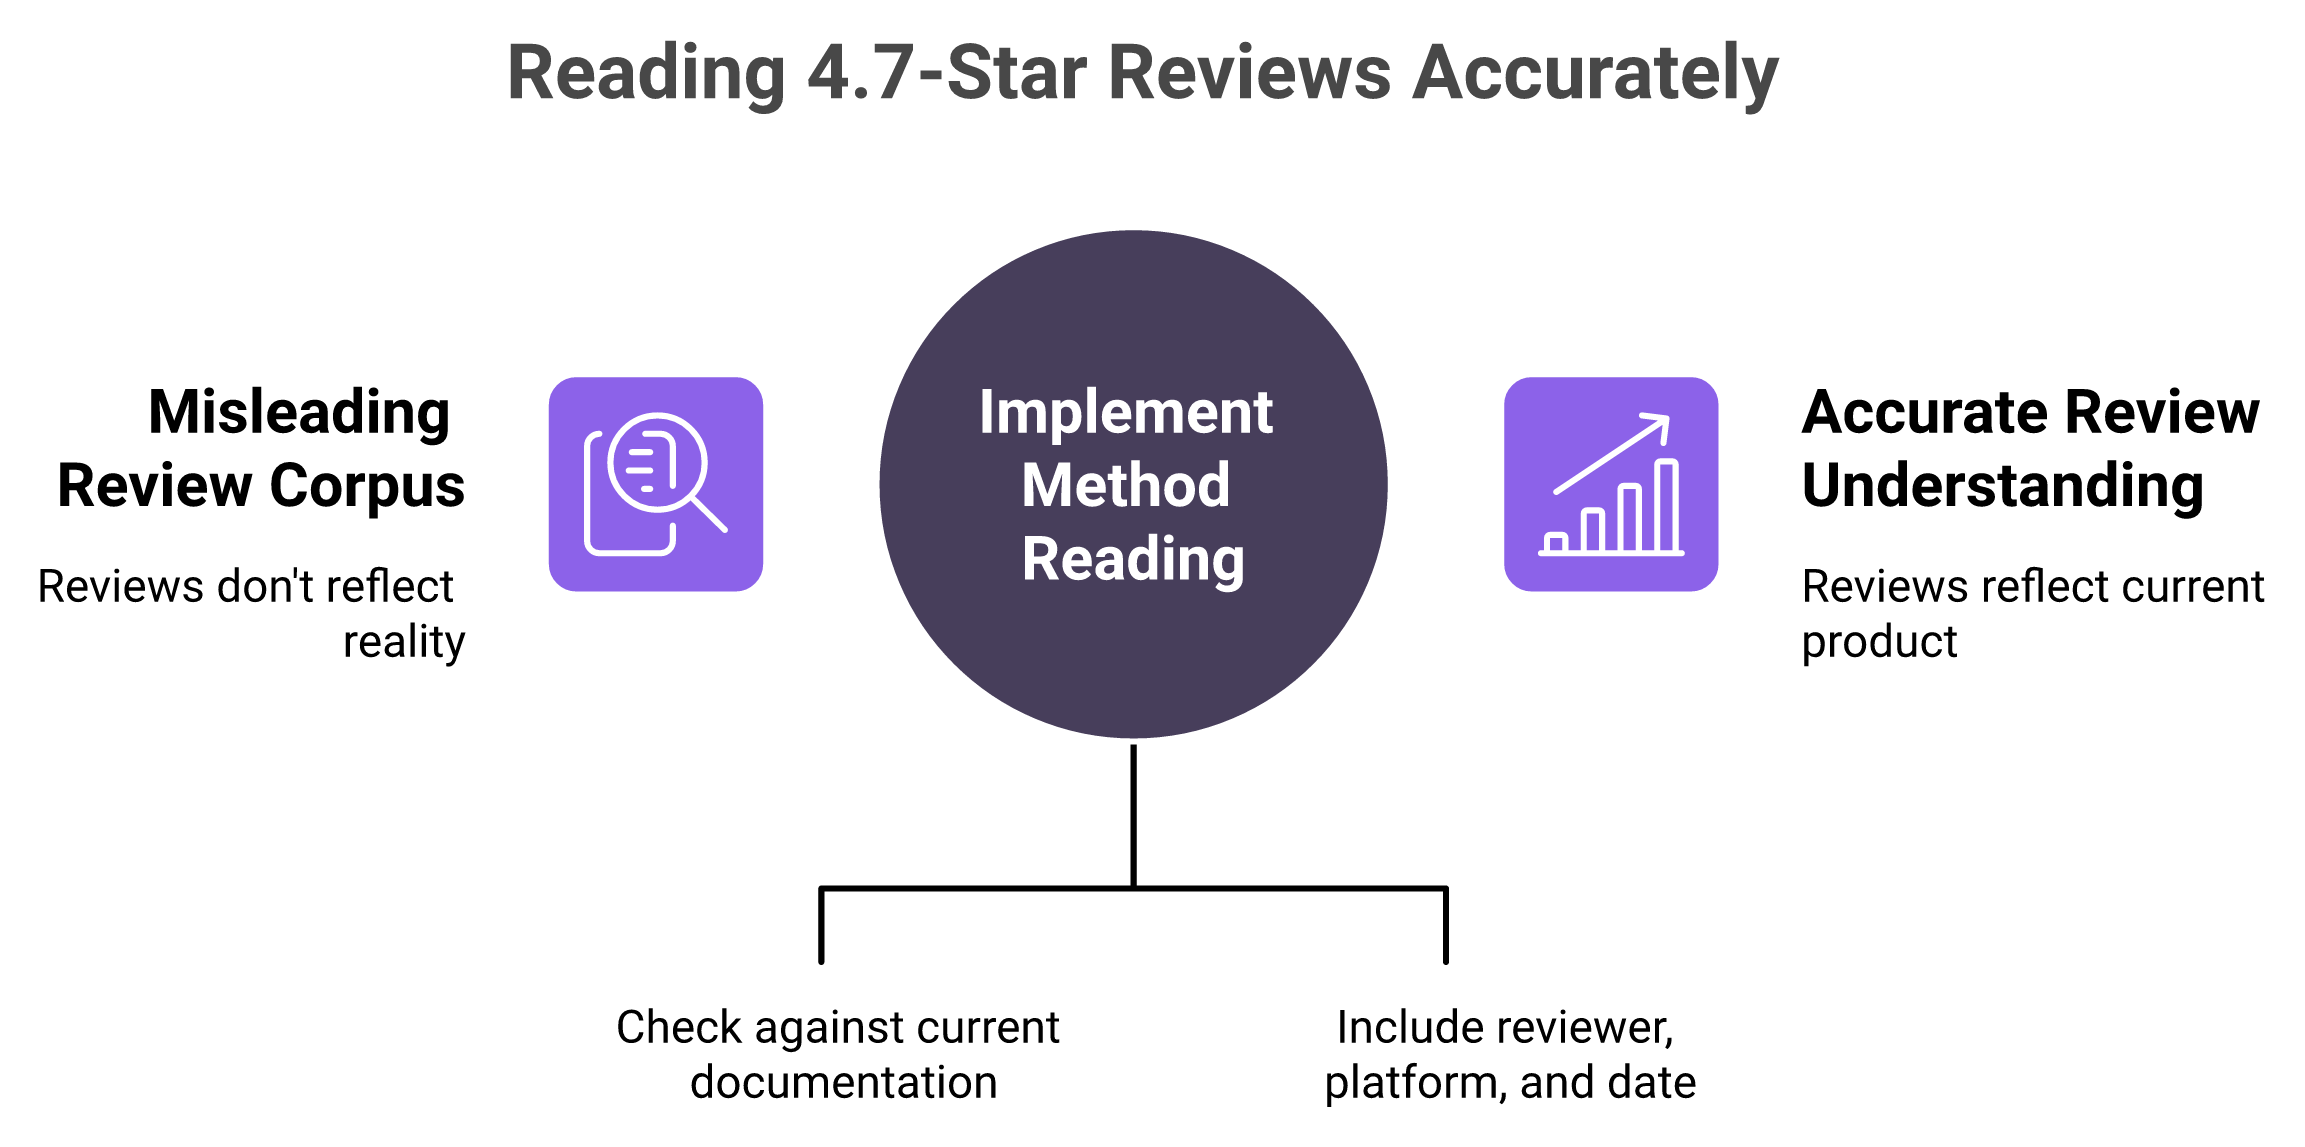
The reading method behind this article: date every quote, then check it against current documentation before acting on it.
✅ The rule this article follows
Every quote here carries its date in the body text, not in a footnote. Every theme is checked against Gong's current published documentation before it is presented as a live issue.
Where a criticism still stands, the current documentation appears beside it. Where the product has moved on, that is said outright. This is slower to write and much harder to argue with. The same test applies to the known Gong limitations that competitors quote most often.
⚠️ The concession you should hold onto
Here is the uncomfortable part, and it is worth saying before any analysis. For a team using Gong broadly, with managers running structured call reviews and two or more modules in daily use, the price is defensible. If that describes you, stop reading and renew.
A satisfied-customer review set is genuinely a poor guide for a prospective buyer. I could be reading this too strongly, but I think the survivorship gap is the single biggest flaw in every "we analysed X reviews" article on this topic, including earlier versions of this one.
"I appreciate how Gong organizes all our chats, videos, and audio with clients into a single source... I found the AI tracker setup to be quite difficult." — Verified reviewer, "Challenging Setup with Valuable AI Tracking" Gong G2 Verified Review [3 Oct 2025]
One reviewer, two verdicts, same paragraph. That is what a 4.7 corpus actually looks like up close.
Q3. What do reviewers complain about most, and does each complaint still hold? [toc=3. Recurring Complaints]
Five themes recur across verified Gong reviews: what the seat now includes; unused breadth, where teams pay for modules nobody opens; add-on cost for Forecast and Engage; setup and admin load; and notification volume. Accuracy and transcription quality are rarely the objection. Every theme needs a date check, because several criticised modules have since been rebuilt, and a 2024 review is evidence about 2024 only.
🗂️ The five themes, with a current-state check
Recurring Gong Complaint Themes and Whether They Still Hold in 2026
Theme
Who raises it
Module
Evidence
Still current in 2026?
Unused breadth
Admins, RevOps
Platform-wide
Karel Bos, TrustRadius, 2024
Yes. Gong has added the Revenue Harness execution layer and Gong Enable, so scope has widened, not narrowed.
Add-on cost for modules
Buyers, managers
Forecast, Engage
Scott T., G2, 2024
Yes. Forecast and Engage remain separately licensed.
Setup and admin load
Admins
AI Trackers, integrations
G2, Oct 2025 and Apr 2026
Yes. TrustRadius scores implementation near 5.7 against support near 8.6.
Export and data access
Analysts, RevOps
Snippets, API
G2, Oct 2025
Partly. Gong exports data; the constraint is gating and format, covered later.
Engage versus dedicated sequencers
AEs
Gong Engage
G2, Jun 2025
Contested. The 2025 complaint predates the 2026 execution-layer release.
📌 Two quotes that carry the pattern
"The additional products like forecast or engage come at an additional cost." — Scott T. Gong G2 Verified Review [2024]
"Gong Engage is awful in every single way compared to outreach. Would not recommend at all, flows are hard to get into, information is not readily available, sequencing is difficult to create and track." — Verified reviewer, "Compared to Outreach....doesn't compare" Gong G2 Verified Review [9 Jun 2025]
That second one is a 1.5-star review, and it is the harshest in the set. It is also fifteen months old and about one module, not the platform. Both facts belong in the same sentence when you quote it. If sequencing is the sticking point, the Gong versus Outreach comparison handles that head-to-head properly.
🔍 One theme, walked all the way through
Take unused breadth, because it is the theme that shows up most and gets analysed least.
The complaint is not that features are missing. It is that a team licenses a platform, uses recording and call review heavily, and never opens the rest. The bill reflects the platform. The value reflects two modules. That pattern is the core argument for revenue tech stack consolidation.
Oliv AI maintains a dated, URL-resolved vault of competitor reviews, which is how each quote here was matched back to an individual review page rather than a product listing. That method is the only reason the "still current" column above can be written honestly.
The practical implication per theme is the same shape. Pull the usage data before the renewal call, not during it. Setup and admin load is the one theme that deserves its own treatment, and it gets one later in this article.
Q4. What are reviewers actually complaining about when they complain about cost? [toc=4. Cost Complaints Decoded]
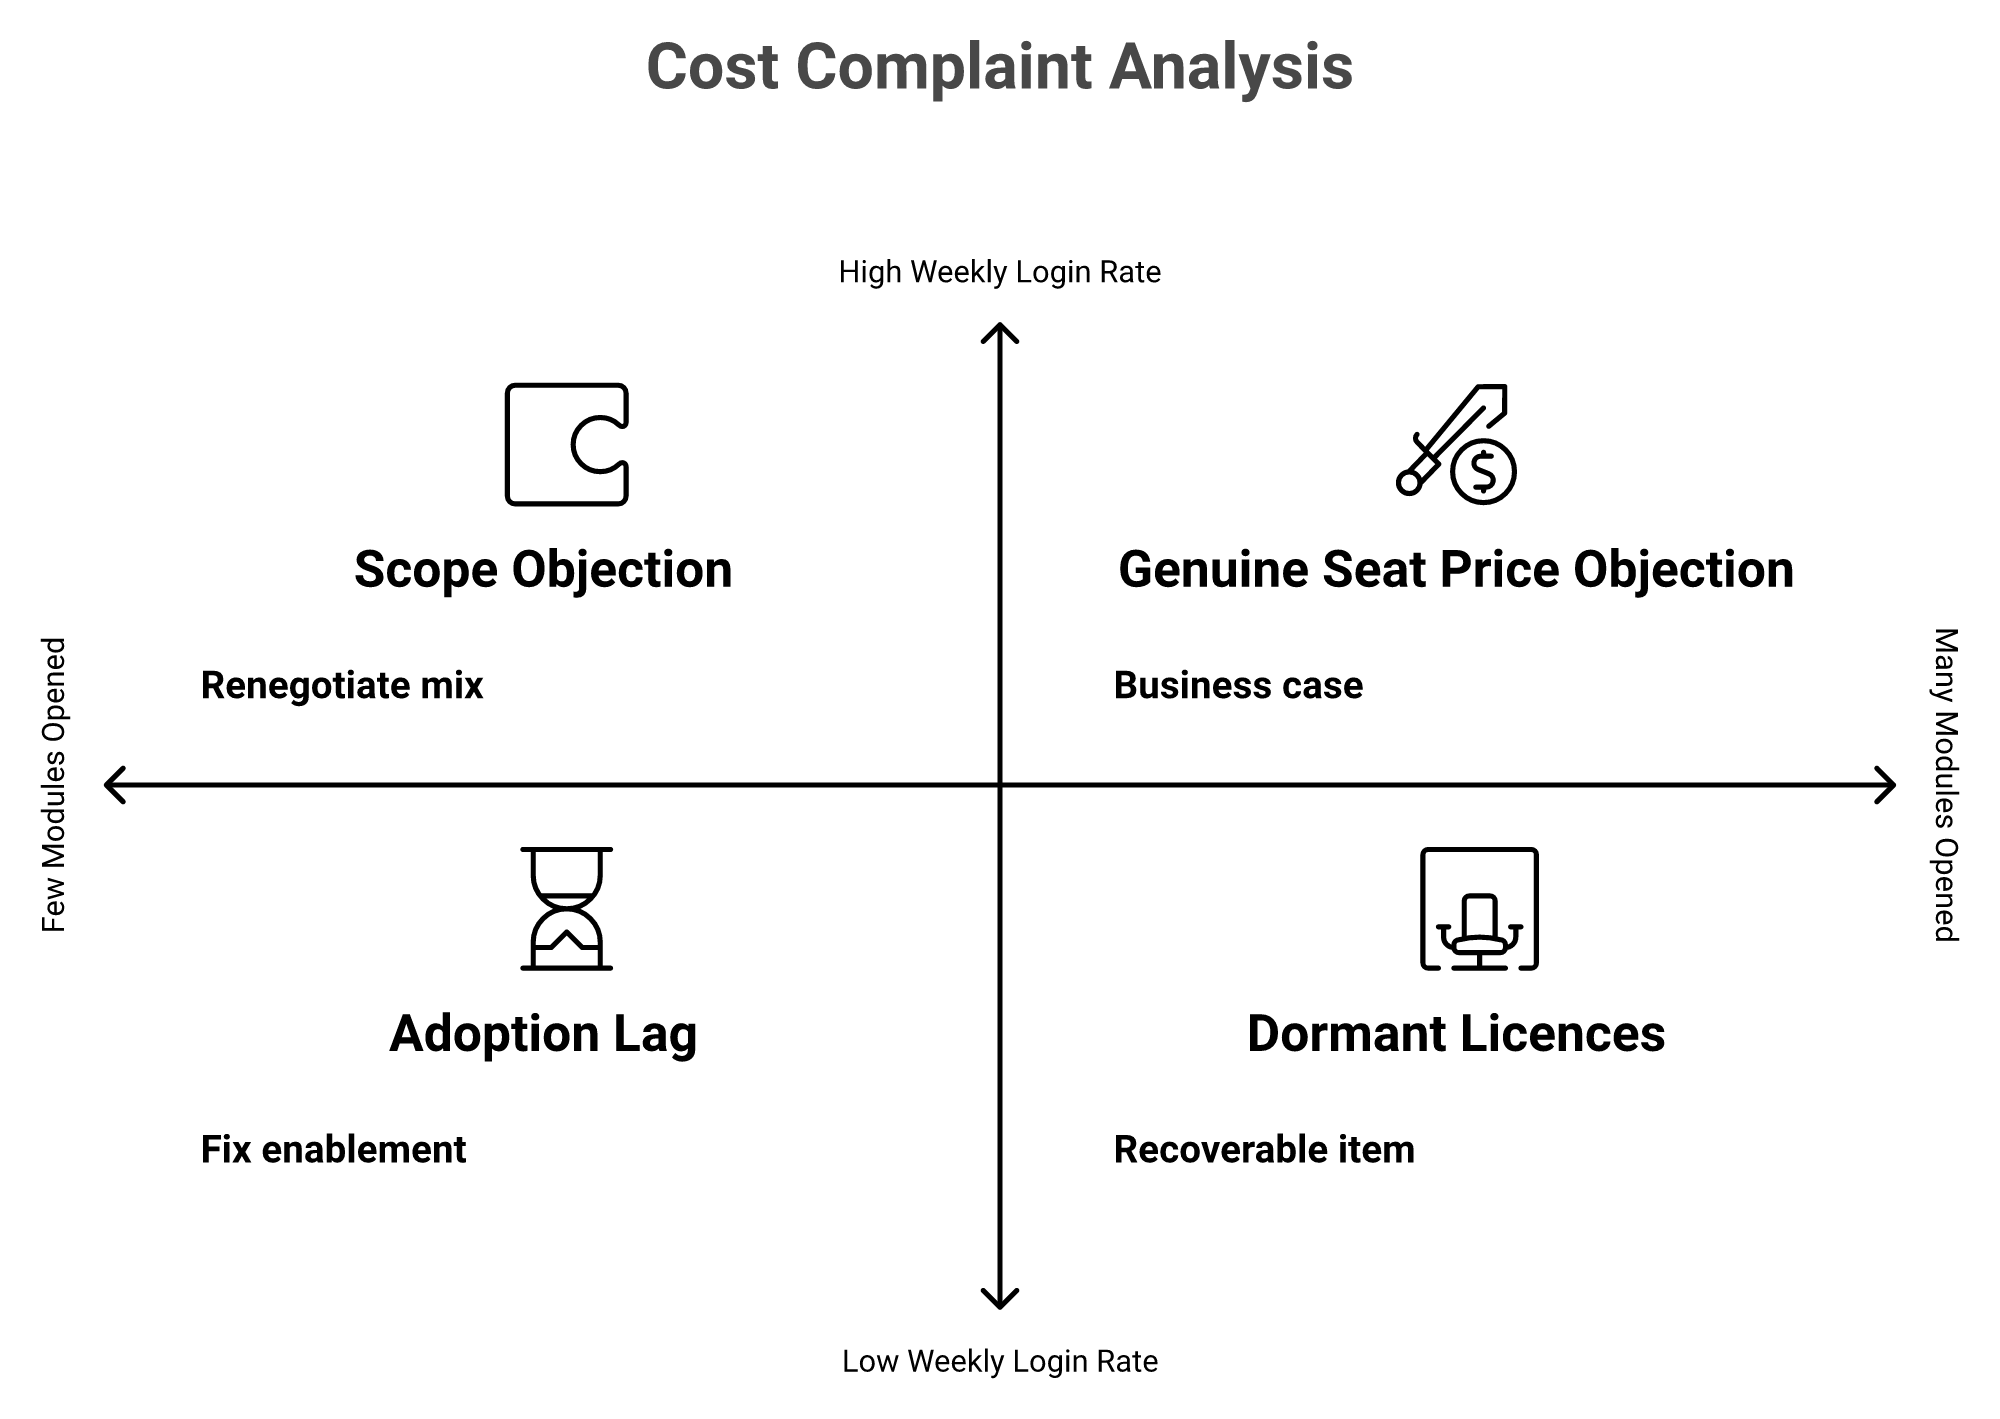
Cost complaints in Gong reviews are three different complaints wearing one label. The first is the seat price itself. The second is scope: Forecast and Engage are separately licensed, so a team can pay for a platform and still not have the module it wanted. The third, and the most common in practice, is licences bought for people who never log in. Gong publishes no figures at all, so any dollar range you read elsewhere is someone's estimate, not a price.
💰 The moment this decides
Somebody says "Gong is expensive," and the renewal conversation ends there. Everyone nods. Nobody has separated what they are actually objecting to.
I have watched that sentence kill a good tool and save a bad one in the same quarter. It is the least useful three words in a renewal room.
❌ Why treating cost complaints as damning is lazy
Every enterprise tool collects price complaints. On its own, that tells you nothing about fit. A cost complaint only becomes evidence when you can say which of the three it is.
Plot your login rate against module usage to find out which cost complaint you actually have before the renewal call.
Worth saying clearly: gong.io/pricing states that licences are per user and that a platform fee exists. It publishes no numbers. Any per-seat range you find in a comparison post is a reconstruction, not a price. Teams working through this usually need a plan to reduce sales tech stack costs before they need a new vendor.
🧮 Complaint one: the seat itself
This is the honest version, and it is the least common in the review corpus. A team uses the product widely, values it, and still finds the per-seat cost high against budget.
There is no clever answer here. Either the outcome justifies the seat or it does not, and that is a business-case question, not a review question. A revenue intelligence ROI calculation settles it faster than another round of reviews.
🧩 Complaint two: scope, not price
This one is different. The reviewer is not saying the platform costs too much. They are saying they paid for a platform and then discovered the module they wanted sits behind another line item.
"The additional products like forecast or engage come at an additional cost." — Scott T. Gong G2 Verified Review [2024]
Metering compounds this. Certain AI features draw from a shared credit pool, so what a seat includes today is not a fixed thing. That mechanic gets its own section next, and the forecasting side is unpacked in the Gong forecasting breakdown.
💸 Complaint three: seats nobody uses
This is the largest one, and it almost never appears as a price complaint. It appears as breadth going unused, which is exactly what Karel Bos described on TrustRadius in 2024.
Before you argue about cost, pull two numbers. First, seats with zero logins in the last thirty days. Second, modules licensed against modules actually opened last quarter.
The dormant-seat count moves renewals more than any feature argument I have ever made. It is also the number almost nobody pulls before the call. Full cost modelling and a quote checklist live in the Gong pricing breakdown; this page stays with what users report about the bill.
Q5. What are Gong credits, and how do they change what a seat includes? [toc=5. Credits and Metering]
Gong credits are a metered, company-wide pool that specific AI features draw from. Documentation from mid-2026 sets the mechanics: roughly ten emails to a credit, a call over ten minutes to a credit, monthly caps that do not roll over, and an API that errors at zero. Question-based AI trackers, AI Ask Anything, AI Briefer, and the MCP server consume credits. Pretrained trackers and viewing existing results do not. Gong states that existing agreements are unchanged, so this is documented metering, not a contract change.
📋 What draws from the pool, and what does not
The list is published, and it is short enough to check in one sitting.
Consumes credits:
Question-based AI trackers, which run continuously on new calls and emails
The AI Ask Anything and AI Briefer APIs
The MCP server, which is the connector that lets outside AI agents query Gong
Does not consume credits:
Pretrained trackers that ship with the product
Viewing results a tracker has already produced
Unpublishing a tracker, which stops its consumption entirely
That last point is the one most admins miss. Creation is free. Running is not.
🧮 A worked example you can check against your own console
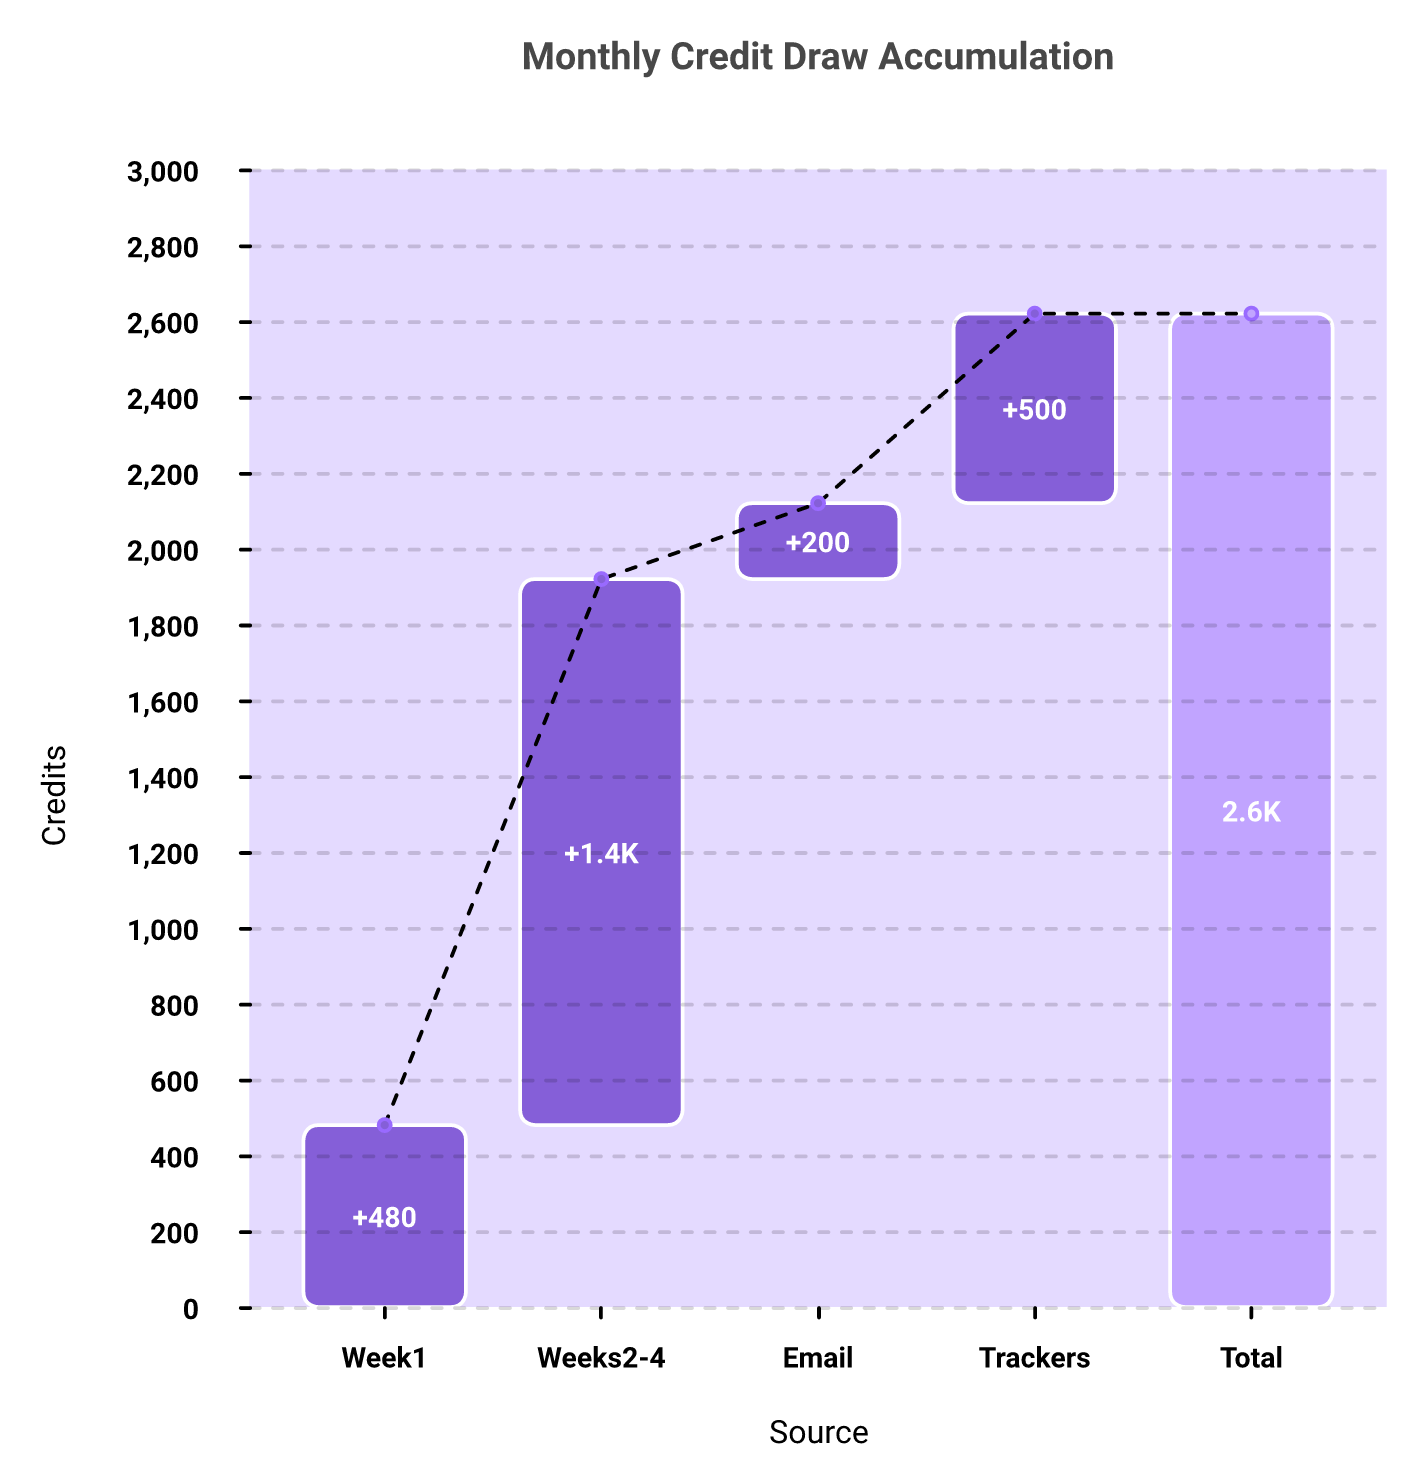
Credit draw compounds from calls, emails, and every extra published tracker, which is why the budgeting unit is no longer the seat.
Take a 40-rep team. Say each rep sits on twelve calls a week that run past ten minutes.
At the documented rate of one credit per call over ten minutes, that is 480 credits a week for call analysis alone, before email. Email adds roughly one credit per ten messages analysed. Multiply by four weeks and you are into four figures monthly, from one published tracker set. Anyone running sales call analytics at that volume should model this before renewal.
Now add three more question-based trackers because three teams each wanted their own. The draw multiplies with them, not with your headcount.
⚠️ What happens when the pool hits zero
The monthly cap does not carry over. Unused credits expire, and the pool is shared across the whole company, not allocated per team.
At zero, the API returns an error and question-based trackers stop processing new data. Nothing breaks loudly. A tracker simply stops producing results, and the person who set it up finds out later. If you have wired Gong into other systems, check the Gong integrations that depend on that API.
I want to be precise about the framing here, because plenty of posts have got it wrong. This is published metering, documented openly by the vendor. It is not a contract breach, and Gong has said existing agreements stand.
💰 Why this changes the renewal conversation
The seat used to be the unit you budgeted. Now the unit is the seat plus a shared pool whose draw depends on how many trackers your admins published, not on how many people you hired.
That is a genuinely different budgeting problem. Headcount is predictable. Tracker sprawl is not. This is exactly the pressure that pushes teams toward reducing sales tech stack costs before the quote lands.
Oliv AI runs its agents against a persistent context graph rather than a shared credit pool that one heavy tracker can drain mid-month, so the unit a RevOps lead budgets stays the unit they signed for. That is a design choice with its own trade-offs, not a free lunch, and we say so plainly.
For the full cost model and a quote checklist, the Gong pricing breakdown carries it. This page stays with the mechanics and what users report.
Q6. Are Gong's Smart Trackers accurate, or just unlimited? [toc=6. Tracker Reality Check]
Gong's AI Tracker detects meaning rather than keywords, and Gong's own documentation says so, which retires the common claim that trackers only match phrases. The real tension is packaging. Gong Foundation advertises unlimited AI trackers, while the credit documentation makes question-based trackers the largest credit consumer and instructs admins to unpublish trackers that no longer provide value. Unlimited to create is not unlimited to run. Audit published trackers quarterly, and unpublish the ones nobody reads.
❌ The claim everyone repeats, including us
The standard line in competitor content is that Gong trackers are glorified keyword search. Miss a synonym, miss the signal.
I have made a version of that argument myself, and earlier drafts of this very page carried it. It does not survive contact with the documentation. The honest version of the critique sits in the write-up on Gong limitations and challenges.
✅ Why the claim is wrong
Gong's help documentation distinguishes between keyword trackers and AI trackers. Question-based AI trackers are described as detecting meaning, not just matching phrases.
You can argue about how well that works on your data. You cannot argue that the feature is keyword matching, because the vendor documents otherwise. Correcting that publicly costs me a talking point and buys the rest of this article some credibility.
⚠️ The narrower claim that does survive
Put the two published sources side by side and a real contradiction appears.
Gong Packaging Versus Gong Credit Documentation on AI Trackers
Source
What it says
Gong Foundation packaging
Unlimited AI Trackers included
Gong credit documentation
Question-based trackers are the biggest credit consumer, and admins should unpublish those no longer providing value
Both statements are true. Together they mean you can create as many trackers as you like, and each published one draws from a finite monthly pool. Unlimited describes creation. Metering governs operation.
⏰ What to do about it on Monday
Three steps, in order:
Export the list of published trackers and note who requested each one.
Check which ones have been opened in the last ninety days.
Unpublish the rest, which stops their credit draw immediately.
Most teams I have seen do this find that a third of their trackers were built for a launch, a competitor scare, or a QBR that happened two years ago. If the goal is methodology scoring rather than theme spotting, auto-scoring MEDDIC, BANT, and SPICED from calls is a cleaner route than tracker sprawl.
🗣️ What reviewers say about living with them
"The AI tracker's ability to identify common themes across different recordings, even those not from my department, very useful... I found the AI tracker setup to be quite difficult, especially concerning the user interface when setting up keywords or smart trackers." — Verified reviewer, "Challenging Setup with Valuable AI Tracking" Gong G2 Verified Review [3 Oct 2025]
"Good for tracking deals, account engagement overall, divided transcript and accurate AI highlights for calls." — Verified reviewer, "Compared to Outreach....doesn't compare" Gong G2 Verified Review [9 Jun 2025]
The second quote comes from a 1.5-star review. Even the harshest reviewer in this set rates the AI highlights as accurate. The complaint is configuration effort, not detection quality.
Tracker depth, including how to write a question-based tracker that earns its credits, sits in the guide to Gong Smart Trackers.
Q7. Why do reviewers rate Gong's support highly but its implementation poorly? [toc=7. Rollout vs Support]
TrustRadius reviewers score Gong's support in the 8.2 to 8.6 range, but its implementation closer to 5.7. That gap tells you where the risk sits. The tickets get answered. The configuration, tracker setup, CRM field mapping, and change management land on whoever owns the tool internally. Before signing or renewing, name a RevOps owner and budget several weeks of their time. Teams that skip this step produce the admin-load complaints that recur across the review set.
📊 What a 2.5-point gap actually means
Support and implementation are scored by the same reviewers, on the same platform, about the same product. So the gap is not sampling noise. It is a structural signal.
High support scores mean the vendor answers when you ask. Low implementation scores mean the work you have to do before you can ask is heavier than expected.
🧰 What the implementation work actually consists of
This is the itemised list that rarely makes it into a demo:
CRM field mapping, so deal data resolves against the right opportunity records
Call recording rules by team, region, and consent requirement
Tracker design, including who owns each one and who reads the output
Scorecard and coaching workflow setup for managers
Integration testing with your sequencer, calendar, and dialler
Change management with reps who did not ask to be recorded
Six workstreams. None of them are hard individually. All of them need one person who owns the whole thing. The mapping step alone usually exposes whatever CRM data quality debt the team has been carrying.
🗣️ What reviewers describe
"I found the AI tracker setup to be quite difficult, especially concerning the user interface when setting up keywords or smart trackers." — Verified reviewer, "Challenging Setup with Valuable AI Tracking" Gong G2 Verified Review [3 Oct 2025]
"Design is user friendly and ensure the elements are visible and with no confusion... Real Time integrations can be time consuming." — Verified reviewer, "User-Friendly Design, but Real-Time Integrations Take Too Long" Gong G2 Verified Review [21 Apr 2026]
Note the second date. April 2026, not 2024. The interface gets praised, and the integration time still gets flagged. That is a complaint that has survived recent releases, which is exactly the test this article applies. The Gong CRM integration path is where most of that time goes.
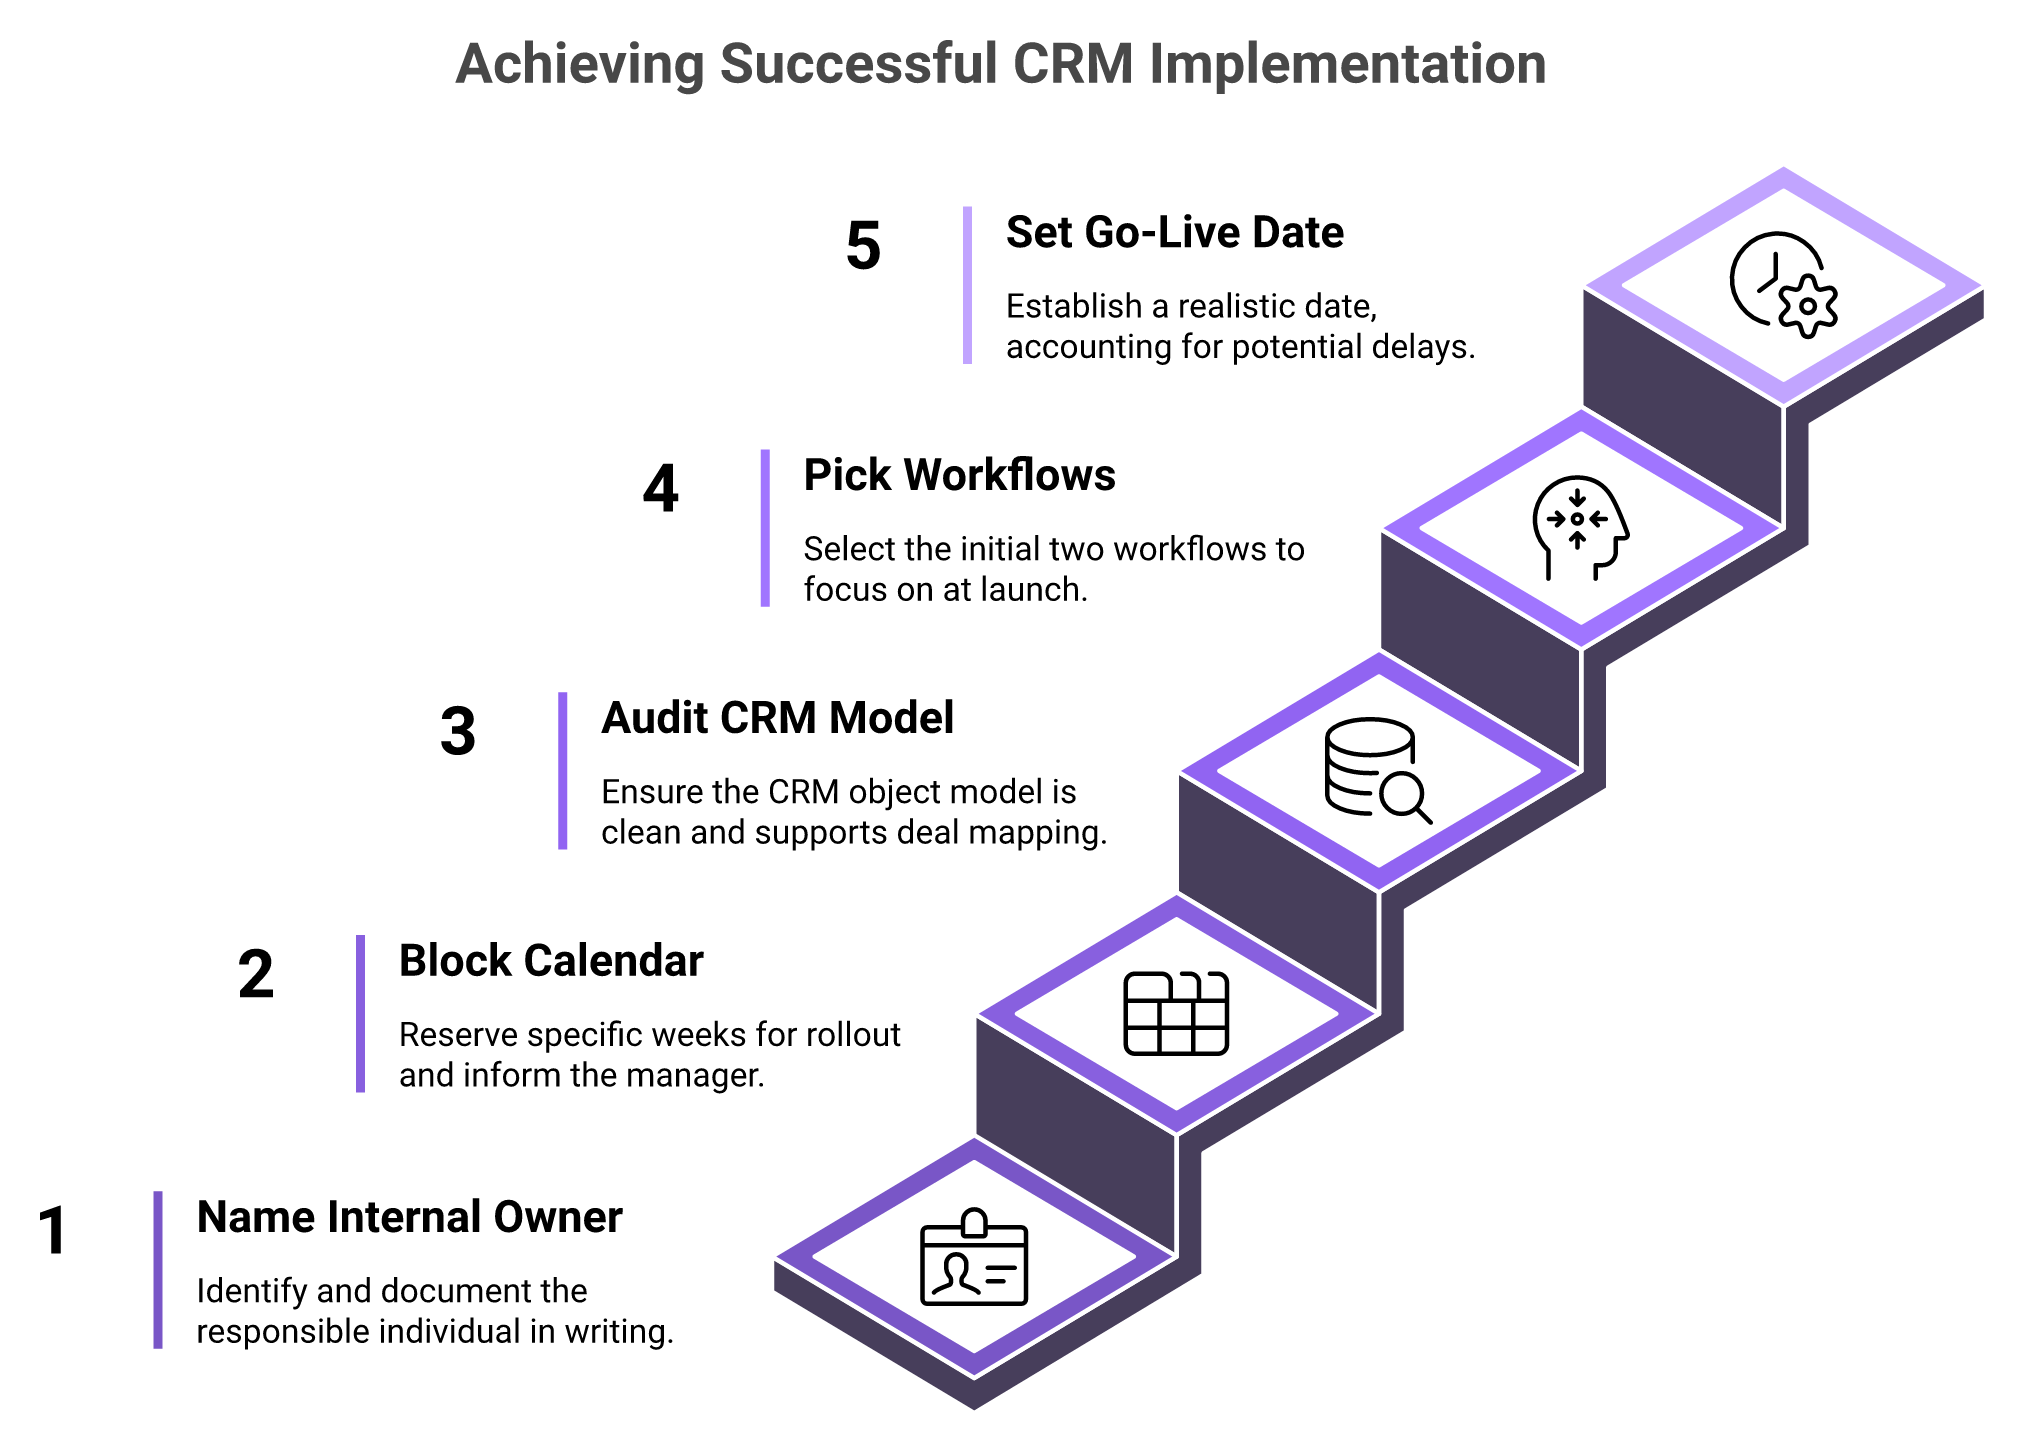
✅ The pre-signature readiness checklist
Reviewers rate support highly and implementation poorly, so these five steps belong in the project plan before the contract is signed.
Run these five before the contract, not after:
Name the internal owner by first name, in writing, in the business case.
Block their calendar for the rollout weeks and tell their manager.
Confirm your CRM object model is clean enough for deal-level mapping.
Agree the first two workflows you will run, and ignore the rest at launch.
Set a go-live date that assumes integration testing takes longer than quoted.
Time-to-value is an owner problem before it is a product problem. Name the human before you sign the paper.
Q8. Which teams get value from Gong, reps, managers or post-sale? [toc=8. Role-by-Role Value]
Managers and RevOps leads review Gong for visibility, coaching scale, and deal boards, and they rate it highly. Individual contributors more often describe notification volume, constant recording, and CRM work the tool relocated rather than removed. Post-sale teams can use Gong, which ships customer success capability and an execution layer, but the review corpus is thin there and the recurring theme is breadth going unused. Licence for the two workflows you will actually run, not for the ones you intend to run later.
👥 Two people, one dashboard, Monday morning
A sales manager opens Gong on Monday and sees a coaching queue. Calls scored, deals flagged, a rep who has not asked a pricing question in three weeks.
An AE on the same team opens the same tool and sees a list of things that were recorded about them. Same platform. Very different feeling. That split is why coaching at scale using AI lands differently by role.
❌ Why top-down seat buying breaks this
The standard rollout buys seats for the whole org because the licence is cheaper in bulk. Adoption is assumed to follow.
It usually does not. Managers adopt fast because the product solves their visibility problem directly. Reps adopt slower, because the value to them is indirect and the cost to them is immediate.
By renewal, you have two populations on one line item, and the average usage number hides both.
✅ What changed, and what to measure now
Usage telemetry has got good enough that you can answer this per person. Pull logins by role for the last thirty days and split the list.
Look at three numbers:
Weekly active managers as a share of manager seats
Weekly active reps as a share of rep seats
Modules opened per role, not per company
If manager adoption is high and rep adoption is low, the tool is working as designed and your seat count is wrong. Those are different problems, and only one of them is Gong's. Tracking them properly is a revenue performance analytics exercise, not a procurement one.
🧩 The post-sale question, answered accurately
Gong is not sales-only. It ships customer success capability, and in June 2026 it launched the Revenue Harness execution layer alongside Gong Enable.
So the honest answer for CS teams is yes, with conditions. The review corpus is genuinely thin for post-sale users, which means you have less peer evidence to lean on. Decide the two CS workflows you will run before you licence anyone, because breadth going unused is the single most repeated theme in this entire review set. Teams weighing this against dedicated tooling should read the comparison of customer success platforms.
"Gong Engage is awful in every single way compared to outreach... flows are hard to get into, information is not readily available, sequencing is difficult to create and track." — Verified reviewer, "Compared to Outreach....doesn't compare" Gong G2 Verified Review [9 Jun 2025]
That second review is a rep's view of a module reps live inside daily. It predates the 2026 execution-layer release, so date it when you quote it. The module itself is unpacked in the explainer on what Gong Engage does.
The failure mode underneath all of this is seats bought for a future state that never arrives. It is the largest recoverable line item in most bloated renewals, and almost nobody audits it until the quote lands.
Q9. Can you get your data out of Gong, and who has to consent to the recording? [toc=9. Data Exit and Consent]
Gong exports data. The accurate limitation is narrower: its MCP server exposes three tools and returns a synthesized answer rather than raw activity data, so an agent querying Gong gets a conclusion, not the rows. Reviewers separately describe bulk snippet download gated behind a plan level. On consent, the EU AI Act's disclosure duty applies from 2 August 2026, and Germany, Austria, and Greece require all-party consent, so a global rollout needs per-country recording settings, not one default.
❌ The myth worth killing first
Plenty of competitor pages claim Gong locks your data in. That claim is contradicted by Gong's own published pages, and repeating it costs you credibility in a procurement conversation.
Gong has export paths. The real questions are about format, gating, and what an AI agent receives when it asks. The security and processing terms are unpacked separately in the note on Gong DPA and security.
🔌 What the MCP server actually returns
MCP stands for Model Context Protocol, the standard that lets outside AI tools query a system directly.
Gong's MCP server exposes three tools and returns a synthesized answer. That means an agent asking about an account gets Gong's conclusion, not the underlying call rows, email records, or activity timestamps.
If you are building your own agent layer on top of your stack, this matters a lot. You can consume Gong's judgment. You cannot easily rebuild it somewhere else. That constraint is the crux of any build versus buy decision on revenue AI.
🗣️ What a reviewer experienced
"I cannot download all the data myself unless we upgrade the plan, which isn't ideal and results in me not fully utilizing Gong. The requirement to download snippets one by one using copy and paste is particularly annoying." — Verified reviewer, "Challenging Setup with Valuable AI Tracking" Gong G2 Verified Review [3 Oct 2025]
"Real Time integrations can be time consuming." — Verified reviewer, "User-Friendly Design, but Real-Time Integrations Take Too Long" Gong G2 Verified Review [21 Apr 2026]
That first quote is a 3-star review from a user who likes the product. It is not a data-lock-in accusation. It is a plan-tier constraint, which is a different thing and easier to solve in a contract. Teams that do decide to move should read the migration from Gong walkthrough first.
⚠️ The consent map nobody puts in a review post
Recording rules are not uniform, and one global default will get you in trouble.
Recording and Disclosure Requirements by Jurisdiction (2026)
Requirement
Where it applies
What it means for rollout
EU AI Act Article 50 disclosure
EU, from 2 August 2026
People must be told they are interacting with AI
All-party consent
Germany, Austria, Greece, and others
Every participant must agree, not just the host
GDPR Article 9
EU
Voiceprints count as biometric data, with stricter handling
Configure recording and disclosure by country, not by org default. If your team sells into Europe, this is a rollout task, not a legal footnote. The wider governance checklist sits in the guide to AI CRM trust and governance for RevOps.
✅ Three things to do before you sign
Run one full export during the evaluation period, and check the format you actually receive.
Write export format, cadence, and destination into the contract, not the email thread.
Audit recording and disclosure settings per country before your first EU quarter.
Test the export while you are happy. Nobody discovers a portability problem on a good day.
Q10. Should you renew Gong, and how do you prove it paid for itself? [toc=10. Renew, Renegotiate or Replace]
Renew if more than half your licensed users log in weekly, managers run structured call reviews on a cadence, and you use at least two modules beyond recording. In that configuration the price is defensible. Renegotiate before you replace if seats are dormant or the credit pool drains on trackers nobody reads. Prove payback with one outcome metric, such as win rate or cycle-time delta, not calls recorded. LinkedIn's 2026 buyer research and Salesforce's State of Sales both point the same way: measure outcomes, and fix CRM data quality first.
💰 The room this decision happens in
The quote lands. Somebody has already forwarded it to finance. A VP says the number out loud and the room goes quiet.
Nobody in that room has pulled the usage export yet. That is almost always true, and it is why these calls go badly.
❌ Why the obvious move is the wrong one
The reflex is an across-the-board seat cut. Trim twenty percent, save the number, move on.
That breaks the thing that was working. Manager adoption is usually high, because coaching queues and deal boards solve their problem directly. Cut evenly and you damage the coaching cadence while leaving the dormant rep seats untouched. If coaching is the value you are protecting, compare it against dedicated sales coaching software before you cut.
✅ The three metrics that settle it
Pull these before the call, not during it:
Weekly active users as a share of licensed seats, split by role
Modules licensed against modules actually opened last quarter
Credit draw by tracker, with the owner's name beside each one
Then apply the rule:
Renew, Renegotiate, or Replace: The Decision Rule
Situation
Decision
Over half log in weekly, two or more modules in use
Renew
High manager use, low rep use, dormant seats
Renegotiate seat count and mix
Low use across roles, credits draining on unread trackers
Evaluate alternatives, but finish the audit first
⏰ The renegotiation checklist
Bring the dormant-seat count as a number, not an impression.
Ask which modules can be dropped and re-added later.
Ask what happens to your credit pool if tracker count falls.
Get renewal uplift terms in writing before you discuss anything else.
⭐ How to prove payback
Adoption is not payback. Calls recorded is not payback. Pick one outcome metric and hold it for two quarters. The mechanics of that sit in the revenue intelligence ROI calculator.
LinkedIn's 2026 buyer research, run with Ipsos across 900-plus B2B buyers, argues for measuring AI by deals progressed rather than activity logged. Salesforce's 2026 State of Sales, covering 4,000-plus sellers, names data quality and admin friction as the top blockers to AI returns. Both point at the same fix: clean the CRM before you expand seats, which is a CRM data strategy problem more than a tooling one.
"The additional products like forecast or engage come at an additional cost." — Scott T. Gong G2 Verified Review [2024]
One honest concession before you act on any of this. The alternatives are not equivalents. If your team is getting real value mid-contract, renegotiate rather than replace, and anchor the decision to your renewal event rather than a calendar month.
Q11. If the complaints are about scope and cost, what does a modular alternative look like? [toc=11. The Modular Alternative]
The recurring criticisms in Gong's review corpus are about scope and cost per outcome, not capability, which points toward modularity rather than replacement. Oliv AI is built as an agentic revenue layer that can sit on top of Gong rather than displace it, so a team mid-contract can add agent-run workflows without unwinding a platform that already works. Oliv AI has no public review corpus of its own, which on a page about reviews is worth stating plainly. Named customers include Sprinto and Triple Whale.
🧭 What eleven sections of review reading actually pointed at
Not accuracy. Not reliability. Not transcription quality.
Scope, cost per outcome, and rollout effort. Every recurring theme in this article traces back to one of those three. That is a shape of problem, and it has a shape of answer.
❌ Why the rip-and-replace pitch fails right now
You are reading this mid-renewal, with a quote open. A vendor telling you to migrate an entire platform is asking you to take on a second project while you are trying to close a first one.
I have made that pitch before and watched it die on the call. It deserved to. The switching cost lands on the same RevOps lead who is already carrying the rollout debt. A straight feature comparison is available in Gong versus Oliv for anyone who does want it.
✅ What changes when work is agent-run instead of app-run
First-generation revenue intelligence surfaces information and leaves the work to a person. Somebody still opens the dashboard, reads the deal board, and updates the record.
Agent-run work inverts that. The system holds context across accounts and opportunities, then executes a defined workflow against it. The person reviews output instead of assembling it. That shift is traced in more depth in the piece on AI agents versus SaaS dashboards.
That distinction is the whole argument, and it is worth being sceptical about. Plenty of vendors say agent and mean automation with a nicer label.
🧩 Where Oliv AI actually sits
Oliv AI runs agents against a continuously updated context graph of accounts and opportunities, drawing on the call and CRM data a team already has, which means it can add orchestration on top of a live Gong deployment rather than requiring a migration first. We think that posture is more useful to a reader mid-renewal than a displacement pitch, and it is checkable rather than aspirational.
Sprinto and Triple Whale use it daily. Oliv AI is SOC 2 Type II certified, GDPR and CCPA compliant, with an open export policy, and the trust documentation is public at trust.oliv.ai. The agent set itself is documented in Oliv AI agents for sales teams.
⚠️ What this page will not claim
Three disclosures, because a page about honest review reading has to hold itself to the same rule.
Oliv AI has no G2 review corpus to set against Gong's 6,694 reviews. That is a real gap, and it is not hidden here.
No price appears in this article, because the figure needs confirming before publication.
No savings number, no migration promise, and no rating. None of those are currently sourceable to a published document.
Oliv AI is also wrong for some buyers. If you want call recording alone, or you run a B2C support team, the category fit is poor and you should say so internally before anyone books a demo.
If you are sitting with a Gong quote and a usage export, that is exactly the conversation worth having. Tell us what your dormant-seat number looks like, and we will tell you honestly whether an agent layer helps. More detail on the RevOps side sits at Oliv for RevOps, and if it is useful, book a walkthrough.
Q1. What do Gong reviews actually say in 2026? [toc=1. The 2026 Verdict]
Gong reviews in 2026 are strongly positive. Gong holds 4.7 out of 5 across roughly 6,694 G2 reviews, 9.1 out of 10 on TrustRadius across more than 1,000 ratings, 4.8 on Capterra, and 4.7 across verified Gartner Peer Insights reviews. Gartner also named Gong a Leader in its 2025 Magic Quadrant for Revenue Action Orchestration. The recurring criticisms are not about accuracy or reliability. They cluster on scope, cost per outcome, and rollout effort. Read them as feedback from people who broadly like the product.
📊 How this review set was read
Most Gong review round-ups never tell you how the quotes were picked. So here is the method first, before any finding.
Four platforms were read: G2, TrustRadius, Capterra, and Gartner Peer Insights. Only reviews that resolve to an individual review URL with a visible date were kept in the analysed subset. Product pages and unlinked quotes were excluded. The population rating is reported separately from that subset, and the two are never mixed.
That distinction matters more than it sounds. A platform average describes thousands of users. A quote describes one person on one day. The same discipline applies when you compare any revenue intelligence platform on peer-review evidence alone.
⭐ The ratings, reconciled in one place
Gong Ratings Across Four Review Platforms (2026)
Platform
Score
Volume
What it tells you
G2
4.7 / 5
~6,694 reviews
Broadest sample, heaviest on mid-market sellers
TrustRadius
9.1 / 10
1,090+ ratings
Deeper written detail, feature-level scoring
Capterra
4.8 / 5
561 reviews
Skews smaller companies
Gartner Peer Insights
4.7 / 5
~371 reviews
Identity-verified, enterprise-weighted
The four platforms agree. That agreement is the finding. When a product scores this consistently across different sampling methods, the quality question is answered, and the remaining questions are about fit and cost.
One number inside TrustRadius is worth pulling out early. Reviewers score Gong's support in the 8.2 to 8.6 range, but its implementation closer to 5.7. The helpdesk is not the weak point. The rollout is, which is why the Gong implementation timeline matters more than most buyers expect.
⚠️ What a single review can and cannot prove
A review proves that one person had one experience, on one date, on one module. Nothing more. It cannot establish how common something is, and it cannot tell you what a vendor charges.
That rule is why this article dates every quote in the body text. Review sites stack five years of releases on one page, so a 2024 complaint about a module Gong has since rebuilt sits beside a 2026 one and looks identical. Reading the current Gong feature set beside an older review is the only way to tell them apart.
"Design is user friendly and ensure the elements are visible and with no confusion... Real Time integrations can be time consuming." — Verified reviewer, "User-Friendly Design, but Real-Time Integrations Take Too Long" Gong G2 Verified Review [21 Apr 2026]
Those two sit at opposite ends of the same story. The product works. The question is how much of it you are actually going to use.
Q2. Why does a 4.7 rating make the complaints more useful, not less? [toc=2. How to Read the Reviews]
When a product averages 4.7, the criticisms that still recur are the ones people who like the tool cannot ignore. That makes them structural, not incidental. The limitation is real and worth stating plainly: buyers who evaluated Gong and chose something else never wrote a review, so the corpus describes users, not the market. Treat every theme as a hypothesis, date it, then check it against Gong's current documentation before you act on it at renewal.
🧾 The scene most readers are actually in
You have a renewal quote open in one tab and six thousand reviews in another. You are not deciding whether conversation intelligence is useful. You decided that two years ago.
You are deciding whether this specific bill is justified, and whether the complaints you are reading are about the product or about the price. Those are different problems with different answers, and the split between revenue intelligence and conversation intelligence is usually where it starts.
❌ Why the normal way of reading reviews fails
The default move is to sort by lowest rating and read the angry ones. It feels efficient. It is close to useless.
Review platforms present a five-year archive as if it were a snapshot. A complaint about a module that shipped in 2023 renders exactly like one written last month. Nothing on the page tells you which criticisms have survived two years of releases.
The reading method behind this article: date every quote, then check it against current documentation before acting on it.
✅ The rule this article follows
Every quote here carries its date in the body text, not in a footnote. Every theme is checked against Gong's current published documentation before it is presented as a live issue.
Where a criticism still stands, the current documentation appears beside it. Where the product has moved on, that is said outright. This is slower to write and much harder to argue with. The same test applies to the known Gong limitations that competitors quote most often.
⚠️ The concession you should hold onto
Here is the uncomfortable part, and it is worth saying before any analysis. For a team using Gong broadly, with managers running structured call reviews and two or more modules in daily use, the price is defensible. If that describes you, stop reading and renew.
A satisfied-customer review set is genuinely a poor guide for a prospective buyer. I could be reading this too strongly, but I think the survivorship gap is the single biggest flaw in every "we analysed X reviews" article on this topic, including earlier versions of this one.
"I appreciate how Gong organizes all our chats, videos, and audio with clients into a single source... I found the AI tracker setup to be quite difficult." — Verified reviewer, "Challenging Setup with Valuable AI Tracking" Gong G2 Verified Review [3 Oct 2025]
One reviewer, two verdicts, same paragraph. That is what a 4.7 corpus actually looks like up close.
Q3. What do reviewers complain about most, and does each complaint still hold? [toc=3. Recurring Complaints]
Five themes recur across verified Gong reviews: what the seat now includes; unused breadth, where teams pay for modules nobody opens; add-on cost for Forecast and Engage; setup and admin load; and notification volume. Accuracy and transcription quality are rarely the objection. Every theme needs a date check, because several criticised modules have since been rebuilt, and a 2024 review is evidence about 2024 only.
🗂️ The five themes, with a current-state check
Recurring Gong Complaint Themes and Whether They Still Hold in 2026
Theme
Who raises it
Module
Evidence
Still current in 2026?
Unused breadth
Admins, RevOps
Platform-wide
Karel Bos, TrustRadius, 2024
Yes. Gong has added the Revenue Harness execution layer and Gong Enable, so scope has widened, not narrowed.
Add-on cost for modules
Buyers, managers
Forecast, Engage
Scott T., G2, 2024
Yes. Forecast and Engage remain separately licensed.
Setup and admin load
Admins
AI Trackers, integrations
G2, Oct 2025 and Apr 2026
Yes. TrustRadius scores implementation near 5.7 against support near 8.6.
Export and data access
Analysts, RevOps
Snippets, API
G2, Oct 2025
Partly. Gong exports data; the constraint is gating and format, covered later.
Engage versus dedicated sequencers
AEs
Gong Engage
G2, Jun 2025
Contested. The 2025 complaint predates the 2026 execution-layer release.
📌 Two quotes that carry the pattern
"The additional products like forecast or engage come at an additional cost." — Scott T. Gong G2 Verified Review [2024]
"Gong Engage is awful in every single way compared to outreach. Would not recommend at all, flows are hard to get into, information is not readily available, sequencing is difficult to create and track." — Verified reviewer, "Compared to Outreach....doesn't compare" Gong G2 Verified Review [9 Jun 2025]
That second one is a 1.5-star review, and it is the harshest in the set. It is also fifteen months old and about one module, not the platform. Both facts belong in the same sentence when you quote it. If sequencing is the sticking point, the Gong versus Outreach comparison handles that head-to-head properly.
🔍 One theme, walked all the way through
Take unused breadth, because it is the theme that shows up most and gets analysed least.
The complaint is not that features are missing. It is that a team licenses a platform, uses recording and call review heavily, and never opens the rest. The bill reflects the platform. The value reflects two modules. That pattern is the core argument for revenue tech stack consolidation.
Oliv AI maintains a dated, URL-resolved vault of competitor reviews, which is how each quote here was matched back to an individual review page rather than a product listing. That method is the only reason the "still current" column above can be written honestly.
The practical implication per theme is the same shape. Pull the usage data before the renewal call, not during it. Setup and admin load is the one theme that deserves its own treatment, and it gets one later in this article.
Q4. What are reviewers actually complaining about when they complain about cost? [toc=4. Cost Complaints Decoded]
Cost complaints in Gong reviews are three different complaints wearing one label. The first is the seat price itself. The second is scope: Forecast and Engage are separately licensed, so a team can pay for a platform and still not have the module it wanted. The third, and the most common in practice, is licences bought for people who never log in. Gong publishes no figures at all, so any dollar range you read elsewhere is someone's estimate, not a price.
💰 The moment this decides
Somebody says "Gong is expensive," and the renewal conversation ends there. Everyone nods. Nobody has separated what they are actually objecting to.
I have watched that sentence kill a good tool and save a bad one in the same quarter. It is the least useful three words in a renewal room.
❌ Why treating cost complaints as damning is lazy
Every enterprise tool collects price complaints. On its own, that tells you nothing about fit. A cost complaint only becomes evidence when you can say which of the three it is.
Plot your login rate against module usage to find out which cost complaint you actually have before the renewal call.
Worth saying clearly: gong.io/pricing states that licences are per user and that a platform fee exists. It publishes no numbers. Any per-seat range you find in a comparison post is a reconstruction, not a price. Teams working through this usually need a plan to reduce sales tech stack costs before they need a new vendor.
🧮 Complaint one: the seat itself
This is the honest version, and it is the least common in the review corpus. A team uses the product widely, values it, and still finds the per-seat cost high against budget.
There is no clever answer here. Either the outcome justifies the seat or it does not, and that is a business-case question, not a review question. A revenue intelligence ROI calculation settles it faster than another round of reviews.
🧩 Complaint two: scope, not price
This one is different. The reviewer is not saying the platform costs too much. They are saying they paid for a platform and then discovered the module they wanted sits behind another line item.
"The additional products like forecast or engage come at an additional cost." — Scott T. Gong G2 Verified Review [2024]
Metering compounds this. Certain AI features draw from a shared credit pool, so what a seat includes today is not a fixed thing. That mechanic gets its own section next, and the forecasting side is unpacked in the Gong forecasting breakdown.
💸 Complaint three: seats nobody uses
This is the largest one, and it almost never appears as a price complaint. It appears as breadth going unused, which is exactly what Karel Bos described on TrustRadius in 2024.
Before you argue about cost, pull two numbers. First, seats with zero logins in the last thirty days. Second, modules licensed against modules actually opened last quarter.
The dormant-seat count moves renewals more than any feature argument I have ever made. It is also the number almost nobody pulls before the call. Full cost modelling and a quote checklist live in the Gong pricing breakdown; this page stays with what users report about the bill.
Q5. What are Gong credits, and how do they change what a seat includes? [toc=5. Credits and Metering]
Gong credits are a metered, company-wide pool that specific AI features draw from. Documentation from mid-2026 sets the mechanics: roughly ten emails to a credit, a call over ten minutes to a credit, monthly caps that do not roll over, and an API that errors at zero. Question-based AI trackers, AI Ask Anything, AI Briefer, and the MCP server consume credits. Pretrained trackers and viewing existing results do not. Gong states that existing agreements are unchanged, so this is documented metering, not a contract change.
📋 What draws from the pool, and what does not
The list is published, and it is short enough to check in one sitting.
Consumes credits:
Question-based AI trackers, which run continuously on new calls and emails
The AI Ask Anything and AI Briefer APIs
The MCP server, which is the connector that lets outside AI agents query Gong
Does not consume credits:
Pretrained trackers that ship with the product
Viewing results a tracker has already produced
Unpublishing a tracker, which stops its consumption entirely
That last point is the one most admins miss. Creation is free. Running is not.
🧮 A worked example you can check against your own console
Credit draw compounds from calls, emails, and every extra published tracker, which is why the budgeting unit is no longer the seat.
Take a 40-rep team. Say each rep sits on twelve calls a week that run past ten minutes.
At the documented rate of one credit per call over ten minutes, that is 480 credits a week for call analysis alone, before email. Email adds roughly one credit per ten messages analysed. Multiply by four weeks and you are into four figures monthly, from one published tracker set. Anyone running sales call analytics at that volume should model this before renewal.
Now add three more question-based trackers because three teams each wanted their own. The draw multiplies with them, not with your headcount.
⚠️ What happens when the pool hits zero
The monthly cap does not carry over. Unused credits expire, and the pool is shared across the whole company, not allocated per team.
At zero, the API returns an error and question-based trackers stop processing new data. Nothing breaks loudly. A tracker simply stops producing results, and the person who set it up finds out later. If you have wired Gong into other systems, check the Gong integrations that depend on that API.
I want to be precise about the framing here, because plenty of posts have got it wrong. This is published metering, documented openly by the vendor. It is not a contract breach, and Gong has said existing agreements stand.
💰 Why this changes the renewal conversation
The seat used to be the unit you budgeted. Now the unit is the seat plus a shared pool whose draw depends on how many trackers your admins published, not on how many people you hired.
That is a genuinely different budgeting problem. Headcount is predictable. Tracker sprawl is not. This is exactly the pressure that pushes teams toward reducing sales tech stack costs before the quote lands.
Oliv AI runs its agents against a persistent context graph rather than a shared credit pool that one heavy tracker can drain mid-month, so the unit a RevOps lead budgets stays the unit they signed for. That is a design choice with its own trade-offs, not a free lunch, and we say so plainly.
For the full cost model and a quote checklist, the Gong pricing breakdown carries it. This page stays with the mechanics and what users report.
Q6. Are Gong's Smart Trackers accurate, or just unlimited? [toc=6. Tracker Reality Check]
Gong's AI Tracker detects meaning rather than keywords, and Gong's own documentation says so, which retires the common claim that trackers only match phrases. The real tension is packaging. Gong Foundation advertises unlimited AI trackers, while the credit documentation makes question-based trackers the largest credit consumer and instructs admins to unpublish trackers that no longer provide value. Unlimited to create is not unlimited to run. Audit published trackers quarterly, and unpublish the ones nobody reads.
❌ The claim everyone repeats, including us
The standard line in competitor content is that Gong trackers are glorified keyword search. Miss a synonym, miss the signal.
I have made a version of that argument myself, and earlier drafts of this very page carried it. It does not survive contact with the documentation. The honest version of the critique sits in the write-up on Gong limitations and challenges.
✅ Why the claim is wrong
Gong's help documentation distinguishes between keyword trackers and AI trackers. Question-based AI trackers are described as detecting meaning, not just matching phrases.
You can argue about how well that works on your data. You cannot argue that the feature is keyword matching, because the vendor documents otherwise. Correcting that publicly costs me a talking point and buys the rest of this article some credibility.
⚠️ The narrower claim that does survive
Put the two published sources side by side and a real contradiction appears.
Gong Packaging Versus Gong Credit Documentation on AI Trackers
Source
What it says
Gong Foundation packaging
Unlimited AI Trackers included
Gong credit documentation
Question-based trackers are the biggest credit consumer, and admins should unpublish those no longer providing value
Both statements are true. Together they mean you can create as many trackers as you like, and each published one draws from a finite monthly pool. Unlimited describes creation. Metering governs operation.
⏰ What to do about it on Monday
Three steps, in order:
Export the list of published trackers and note who requested each one.
Check which ones have been opened in the last ninety days.
Unpublish the rest, which stops their credit draw immediately.
Most teams I have seen do this find that a third of their trackers were built for a launch, a competitor scare, or a QBR that happened two years ago. If the goal is methodology scoring rather than theme spotting, auto-scoring MEDDIC, BANT, and SPICED from calls is a cleaner route than tracker sprawl.
🗣️ What reviewers say about living with them
"The AI tracker's ability to identify common themes across different recordings, even those not from my department, very useful... I found the AI tracker setup to be quite difficult, especially concerning the user interface when setting up keywords or smart trackers." — Verified reviewer, "Challenging Setup with Valuable AI Tracking" Gong G2 Verified Review [3 Oct 2025]
"Good for tracking deals, account engagement overall, divided transcript and accurate AI highlights for calls." — Verified reviewer, "Compared to Outreach....doesn't compare" Gong G2 Verified Review [9 Jun 2025]
The second quote comes from a 1.5-star review. Even the harshest reviewer in this set rates the AI highlights as accurate. The complaint is configuration effort, not detection quality.
Tracker depth, including how to write a question-based tracker that earns its credits, sits in the guide to Gong Smart Trackers.
Q7. Why do reviewers rate Gong's support highly but its implementation poorly? [toc=7. Rollout vs Support]
TrustRadius reviewers score Gong's support in the 8.2 to 8.6 range, but its implementation closer to 5.7. That gap tells you where the risk sits. The tickets get answered. The configuration, tracker setup, CRM field mapping, and change management land on whoever owns the tool internally. Before signing or renewing, name a RevOps owner and budget several weeks of their time. Teams that skip this step produce the admin-load complaints that recur across the review set.
📊 What a 2.5-point gap actually means
Support and implementation are scored by the same reviewers, on the same platform, about the same product. So the gap is not sampling noise. It is a structural signal.
High support scores mean the vendor answers when you ask. Low implementation scores mean the work you have to do before you can ask is heavier than expected.
🧰 What the implementation work actually consists of
This is the itemised list that rarely makes it into a demo:
CRM field mapping, so deal data resolves against the right opportunity records
Call recording rules by team, region, and consent requirement
Tracker design, including who owns each one and who reads the output
Scorecard and coaching workflow setup for managers
Integration testing with your sequencer, calendar, and dialler
Change management with reps who did not ask to be recorded
Six workstreams. None of them are hard individually. All of them need one person who owns the whole thing. The mapping step alone usually exposes whatever CRM data quality debt the team has been carrying.
🗣️ What reviewers describe
"I found the AI tracker setup to be quite difficult, especially concerning the user interface when setting up keywords or smart trackers." — Verified reviewer, "Challenging Setup with Valuable AI Tracking" Gong G2 Verified Review [3 Oct 2025]
"Design is user friendly and ensure the elements are visible and with no confusion... Real Time integrations can be time consuming." — Verified reviewer, "User-Friendly Design, but Real-Time Integrations Take Too Long" Gong G2 Verified Review [21 Apr 2026]
Note the second date. April 2026, not 2024. The interface gets praised, and the integration time still gets flagged. That is a complaint that has survived recent releases, which is exactly the test this article applies. The Gong CRM integration path is where most of that time goes.
✅ The pre-signature readiness checklist
Reviewers rate support highly and implementation poorly, so these five steps belong in the project plan before the contract is signed.
Run these five before the contract, not after:
Name the internal owner by first name, in writing, in the business case.
Block their calendar for the rollout weeks and tell their manager.
Confirm your CRM object model is clean enough for deal-level mapping.
Agree the first two workflows you will run, and ignore the rest at launch.
Set a go-live date that assumes integration testing takes longer than quoted.
Time-to-value is an owner problem before it is a product problem. Name the human before you sign the paper.
Q8. Which teams get value from Gong, reps, managers or post-sale? [toc=8. Role-by-Role Value]
Managers and RevOps leads review Gong for visibility, coaching scale, and deal boards, and they rate it highly. Individual contributors more often describe notification volume, constant recording, and CRM work the tool relocated rather than removed. Post-sale teams can use Gong, which ships customer success capability and an execution layer, but the review corpus is thin there and the recurring theme is breadth going unused. Licence for the two workflows you will actually run, not for the ones you intend to run later.
👥 Two people, one dashboard, Monday morning
A sales manager opens Gong on Monday and sees a coaching queue. Calls scored, deals flagged, a rep who has not asked a pricing question in three weeks.
An AE on the same team opens the same tool and sees a list of things that were recorded about them. Same platform. Very different feeling. That split is why coaching at scale using AI lands differently by role.
❌ Why top-down seat buying breaks this
The standard rollout buys seats for the whole org because the licence is cheaper in bulk. Adoption is assumed to follow.
It usually does not. Managers adopt fast because the product solves their visibility problem directly. Reps adopt slower, because the value to them is indirect and the cost to them is immediate.
By renewal, you have two populations on one line item, and the average usage number hides both.
✅ What changed, and what to measure now
Usage telemetry has got good enough that you can answer this per person. Pull logins by role for the last thirty days and split the list.
Look at three numbers:
Weekly active managers as a share of manager seats
Weekly active reps as a share of rep seats
Modules opened per role, not per company
If manager adoption is high and rep adoption is low, the tool is working as designed and your seat count is wrong. Those are different problems, and only one of them is Gong's. Tracking them properly is a revenue performance analytics exercise, not a procurement one.
🧩 The post-sale question, answered accurately
Gong is not sales-only. It ships customer success capability, and in June 2026 it launched the Revenue Harness execution layer alongside Gong Enable.
So the honest answer for CS teams is yes, with conditions. The review corpus is genuinely thin for post-sale users, which means you have less peer evidence to lean on. Decide the two CS workflows you will run before you licence anyone, because breadth going unused is the single most repeated theme in this entire review set. Teams weighing this against dedicated tooling should read the comparison of customer success platforms.
"Gong Engage is awful in every single way compared to outreach... flows are hard to get into, information is not readily available, sequencing is difficult to create and track." — Verified reviewer, "Compared to Outreach....doesn't compare" Gong G2 Verified Review [9 Jun 2025]
That second review is a rep's view of a module reps live inside daily. It predates the 2026 execution-layer release, so date it when you quote it. The module itself is unpacked in the explainer on what Gong Engage does.
The failure mode underneath all of this is seats bought for a future state that never arrives. It is the largest recoverable line item in most bloated renewals, and almost nobody audits it until the quote lands.
Q9. Can you get your data out of Gong, and who has to consent to the recording? [toc=9. Data Exit and Consent]
Gong exports data. The accurate limitation is narrower: its MCP server exposes three tools and returns a synthesized answer rather than raw activity data, so an agent querying Gong gets a conclusion, not the rows. Reviewers separately describe bulk snippet download gated behind a plan level. On consent, the EU AI Act's disclosure duty applies from 2 August 2026, and Germany, Austria, and Greece require all-party consent, so a global rollout needs per-country recording settings, not one default.
❌ The myth worth killing first
Plenty of competitor pages claim Gong locks your data in. That claim is contradicted by Gong's own published pages, and repeating it costs you credibility in a procurement conversation.
Gong has export paths. The real questions are about format, gating, and what an AI agent receives when it asks. The security and processing terms are unpacked separately in the note on Gong DPA and security.
🔌 What the MCP server actually returns
MCP stands for Model Context Protocol, the standard that lets outside AI tools query a system directly.
Gong's MCP server exposes three tools and returns a synthesized answer. That means an agent asking about an account gets Gong's conclusion, not the underlying call rows, email records, or activity timestamps.
If you are building your own agent layer on top of your stack, this matters a lot. You can consume Gong's judgment. You cannot easily rebuild it somewhere else. That constraint is the crux of any build versus buy decision on revenue AI.
🗣️ What a reviewer experienced
"I cannot download all the data myself unless we upgrade the plan, which isn't ideal and results in me not fully utilizing Gong. The requirement to download snippets one by one using copy and paste is particularly annoying." — Verified reviewer, "Challenging Setup with Valuable AI Tracking" Gong G2 Verified Review [3 Oct 2025]
"Real Time integrations can be time consuming." — Verified reviewer, "User-Friendly Design, but Real-Time Integrations Take Too Long" Gong G2 Verified Review [21 Apr 2026]
That first quote is a 3-star review from a user who likes the product. It is not a data-lock-in accusation. It is a plan-tier constraint, which is a different thing and easier to solve in a contract. Teams that do decide to move should read the migration from Gong walkthrough first.
⚠️ The consent map nobody puts in a review post
Recording rules are not uniform, and one global default will get you in trouble.
Recording and Disclosure Requirements by Jurisdiction (2026)
Requirement
Where it applies
What it means for rollout
EU AI Act Article 50 disclosure
EU, from 2 August 2026
People must be told they are interacting with AI
All-party consent
Germany, Austria, Greece, and others
Every participant must agree, not just the host
GDPR Article 9
EU
Voiceprints count as biometric data, with stricter handling
Configure recording and disclosure by country, not by org default. If your team sells into Europe, this is a rollout task, not a legal footnote. The wider governance checklist sits in the guide to AI CRM trust and governance for RevOps.
✅ Three things to do before you sign
Run one full export during the evaluation period, and check the format you actually receive.
Write export format, cadence, and destination into the contract, not the email thread.
Audit recording and disclosure settings per country before your first EU quarter.
Test the export while you are happy. Nobody discovers a portability problem on a good day.
Q10. Should you renew Gong, and how do you prove it paid for itself? [toc=10. Renew, Renegotiate or Replace]
Renew if more than half your licensed users log in weekly, managers run structured call reviews on a cadence, and you use at least two modules beyond recording. In that configuration the price is defensible. Renegotiate before you replace if seats are dormant or the credit pool drains on trackers nobody reads. Prove payback with one outcome metric, such as win rate or cycle-time delta, not calls recorded. LinkedIn's 2026 buyer research and Salesforce's State of Sales both point the same way: measure outcomes, and fix CRM data quality first.
💰 The room this decision happens in
The quote lands. Somebody has already forwarded it to finance. A VP says the number out loud and the room goes quiet.
Nobody in that room has pulled the usage export yet. That is almost always true, and it is why these calls go badly.
❌ Why the obvious move is the wrong one
The reflex is an across-the-board seat cut. Trim twenty percent, save the number, move on.
That breaks the thing that was working. Manager adoption is usually high, because coaching queues and deal boards solve their problem directly. Cut evenly and you damage the coaching cadence while leaving the dormant rep seats untouched. If coaching is the value you are protecting, compare it against dedicated sales coaching software before you cut.
✅ The three metrics that settle it
Pull these before the call, not during it:
Weekly active users as a share of licensed seats, split by role
Modules licensed against modules actually opened last quarter
Credit draw by tracker, with the owner's name beside each one
Then apply the rule:
Renew, Renegotiate, or Replace: The Decision Rule
Situation
Decision
Over half log in weekly, two or more modules in use
Renew
High manager use, low rep use, dormant seats
Renegotiate seat count and mix
Low use across roles, credits draining on unread trackers
Evaluate alternatives, but finish the audit first
⏰ The renegotiation checklist
Bring the dormant-seat count as a number, not an impression.
Ask which modules can be dropped and re-added later.
Ask what happens to your credit pool if tracker count falls.
Get renewal uplift terms in writing before you discuss anything else.
⭐ How to prove payback
Adoption is not payback. Calls recorded is not payback. Pick one outcome metric and hold it for two quarters. The mechanics of that sit in the revenue intelligence ROI calculator.
LinkedIn's 2026 buyer research, run with Ipsos across 900-plus B2B buyers, argues for measuring AI by deals progressed rather than activity logged. Salesforce's 2026 State of Sales, covering 4,000-plus sellers, names data quality and admin friction as the top blockers to AI returns. Both point at the same fix: clean the CRM before you expand seats, which is a CRM data strategy problem more than a tooling one.
"The additional products like forecast or engage come at an additional cost." — Scott T. Gong G2 Verified Review [2024]
One honest concession before you act on any of this. The alternatives are not equivalents. If your team is getting real value mid-contract, renegotiate rather than replace, and anchor the decision to your renewal event rather than a calendar month.
Q11. If the complaints are about scope and cost, what does a modular alternative look like? [toc=11. The Modular Alternative]
The recurring criticisms in Gong's review corpus are about scope and cost per outcome, not capability, which points toward modularity rather than replacement. Oliv AI is built as an agentic revenue layer that can sit on top of Gong rather than displace it, so a team mid-contract can add agent-run workflows without unwinding a platform that already works. Oliv AI has no public review corpus of its own, which on a page about reviews is worth stating plainly. Named customers include Sprinto and Triple Whale.
🧭 What eleven sections of review reading actually pointed at
Not accuracy. Not reliability. Not transcription quality.
Scope, cost per outcome, and rollout effort. Every recurring theme in this article traces back to one of those three. That is a shape of problem, and it has a shape of answer.
❌ Why the rip-and-replace pitch fails right now
You are reading this mid-renewal, with a quote open. A vendor telling you to migrate an entire platform is asking you to take on a second project while you are trying to close a first one.
I have made that pitch before and watched it die on the call. It deserved to. The switching cost lands on the same RevOps lead who is already carrying the rollout debt. A straight feature comparison is available in Gong versus Oliv for anyone who does want it.
✅ What changes when work is agent-run instead of app-run
First-generation revenue intelligence surfaces information and leaves the work to a person. Somebody still opens the dashboard, reads the deal board, and updates the record.
Agent-run work inverts that. The system holds context across accounts and opportunities, then executes a defined workflow against it. The person reviews output instead of assembling it. That shift is traced in more depth in the piece on AI agents versus SaaS dashboards.
That distinction is the whole argument, and it is worth being sceptical about. Plenty of vendors say agent and mean automation with a nicer label.
🧩 Where Oliv AI actually sits
Oliv AI runs agents against a continuously updated context graph of accounts and opportunities, drawing on the call and CRM data a team already has, which means it can add orchestration on top of a live Gong deployment rather than requiring a migration first. We think that posture is more useful to a reader mid-renewal than a displacement pitch, and it is checkable rather than aspirational.
Sprinto and Triple Whale use it daily. Oliv AI is SOC 2 Type II certified, GDPR and CCPA compliant, with an open export policy, and the trust documentation is public at trust.oliv.ai. The agent set itself is documented in Oliv AI agents for sales teams.
⚠️ What this page will not claim
Three disclosures, because a page about honest review reading has to hold itself to the same rule.
Oliv AI has no G2 review corpus to set against Gong's 6,694 reviews. That is a real gap, and it is not hidden here.
No price appears in this article, because the figure needs confirming before publication.
No savings number, no migration promise, and no rating. None of those are currently sourceable to a published document.
Oliv AI is also wrong for some buyers. If you want call recording alone, or you run a B2C support team, the category fit is poor and you should say so internally before anyone books a demo.
If you are sitting with a Gong quote and a usage export, that is exactly the conversation worth having. Tell us what your dormant-seat number looks like, and we will tell you honestly whether an agent layer helps. More detail on the RevOps side sits at Oliv for RevOps, and if it is useful, book a walkthrough.
Q1. What do Gong reviews actually say in 2026? [toc=1. The 2026 Verdict]
Gong reviews in 2026 are strongly positive. Gong holds 4.7 out of 5 across roughly 6,694 G2 reviews, 9.1 out of 10 on TrustRadius across more than 1,000 ratings, 4.8 on Capterra, and 4.7 across verified Gartner Peer Insights reviews. Gartner also named Gong a Leader in its 2025 Magic Quadrant for Revenue Action Orchestration. The recurring criticisms are not about accuracy or reliability. They cluster on scope, cost per outcome, and rollout effort. Read them as feedback from people who broadly like the product.
📊 How this review set was read
Most Gong review round-ups never tell you how the quotes were picked. So here is the method first, before any finding.
Four platforms were read: G2, TrustRadius, Capterra, and Gartner Peer Insights. Only reviews that resolve to an individual review URL with a visible date were kept in the analysed subset. Product pages and unlinked quotes were excluded. The population rating is reported separately from that subset, and the two are never mixed.
That distinction matters more than it sounds. A platform average describes thousands of users. A quote describes one person on one day. The same discipline applies when you compare any revenue intelligence platform on peer-review evidence alone.
⭐ The ratings, reconciled in one place
Gong Ratings Across Four Review Platforms (2026)
Platform
Score
Volume
What it tells you
G2
4.7 / 5
~6,694 reviews
Broadest sample, heaviest on mid-market sellers
TrustRadius
9.1 / 10
1,090+ ratings
Deeper written detail, feature-level scoring
Capterra
4.8 / 5
561 reviews
Skews smaller companies
Gartner Peer Insights
4.7 / 5
~371 reviews
Identity-verified, enterprise-weighted
The four platforms agree. That agreement is the finding. When a product scores this consistently across different sampling methods, the quality question is answered, and the remaining questions are about fit and cost.
One number inside TrustRadius is worth pulling out early. Reviewers score Gong's support in the 8.2 to 8.6 range, but its implementation closer to 5.7. The helpdesk is not the weak point. The rollout is, which is why the Gong implementation timeline matters more than most buyers expect.
⚠️ What a single review can and cannot prove
A review proves that one person had one experience, on one date, on one module. Nothing more. It cannot establish how common something is, and it cannot tell you what a vendor charges.
That rule is why this article dates every quote in the body text. Review sites stack five years of releases on one page, so a 2024 complaint about a module Gong has since rebuilt sits beside a 2026 one and looks identical. Reading the current Gong feature set beside an older review is the only way to tell them apart.
"Design is user friendly and ensure the elements are visible and with no confusion... Real Time integrations can be time consuming." — Verified reviewer, "User-Friendly Design, but Real-Time Integrations Take Too Long" Gong G2 Verified Review [21 Apr 2026]
Those two sit at opposite ends of the same story. The product works. The question is how much of it you are actually going to use.
Q2. Why does a 4.7 rating make the complaints more useful, not less? [toc=2. How to Read the Reviews]
When a product averages 4.7, the criticisms that still recur are the ones people who like the tool cannot ignore. That makes them structural, not incidental. The limitation is real and worth stating plainly: buyers who evaluated Gong and chose something else never wrote a review, so the corpus describes users, not the market. Treat every theme as a hypothesis, date it, then check it against Gong's current documentation before you act on it at renewal.
🧾 The scene most readers are actually in
You have a renewal quote open in one tab and six thousand reviews in another. You are not deciding whether conversation intelligence is useful. You decided that two years ago.
You are deciding whether this specific bill is justified, and whether the complaints you are reading are about the product or about the price. Those are different problems with different answers, and the split between revenue intelligence and conversation intelligence is usually where it starts.
❌ Why the normal way of reading reviews fails
The default move is to sort by lowest rating and read the angry ones. It feels efficient. It is close to useless.
Review platforms present a five-year archive as if it were a snapshot. A complaint about a module that shipped in 2023 renders exactly like one written last month. Nothing on the page tells you which criticisms have survived two years of releases.
The reading method behind this article: date every quote, then check it against current documentation before acting on it.
✅ The rule this article follows
Every quote here carries its date in the body text, not in a footnote. Every theme is checked against Gong's current published documentation before it is presented as a live issue.
Where a criticism still stands, the current documentation appears beside it. Where the product has moved on, that is said outright. This is slower to write and much harder to argue with. The same test applies to the known Gong limitations that competitors quote most often.
⚠️ The concession you should hold onto
Here is the uncomfortable part, and it is worth saying before any analysis. For a team using Gong broadly, with managers running structured call reviews and two or more modules in daily use, the price is defensible. If that describes you, stop reading and renew.
A satisfied-customer review set is genuinely a poor guide for a prospective buyer. I could be reading this too strongly, but I think the survivorship gap is the single biggest flaw in every "we analysed X reviews" article on this topic, including earlier versions of this one.
"I appreciate how Gong organizes all our chats, videos, and audio with clients into a single source... I found the AI tracker setup to be quite difficult." — Verified reviewer, "Challenging Setup with Valuable AI Tracking" Gong G2 Verified Review [3 Oct 2025]
One reviewer, two verdicts, same paragraph. That is what a 4.7 corpus actually looks like up close.
Q3. What do reviewers complain about most, and does each complaint still hold? [toc=3. Recurring Complaints]
Five themes recur across verified Gong reviews: what the seat now includes; unused breadth, where teams pay for modules nobody opens; add-on cost for Forecast and Engage; setup and admin load; and notification volume. Accuracy and transcription quality are rarely the objection. Every theme needs a date check, because several criticised modules have since been rebuilt, and a 2024 review is evidence about 2024 only.
🗂️ The five themes, with a current-state check
Recurring Gong Complaint Themes and Whether They Still Hold in 2026
Theme
Who raises it
Module
Evidence
Still current in 2026?
Unused breadth
Admins, RevOps
Platform-wide
Karel Bos, TrustRadius, 2024
Yes. Gong has added the Revenue Harness execution layer and Gong Enable, so scope has widened, not narrowed.
Add-on cost for modules
Buyers, managers
Forecast, Engage
Scott T., G2, 2024
Yes. Forecast and Engage remain separately licensed.
Setup and admin load
Admins
AI Trackers, integrations
G2, Oct 2025 and Apr 2026
Yes. TrustRadius scores implementation near 5.7 against support near 8.6.
Export and data access
Analysts, RevOps
Snippets, API
G2, Oct 2025
Partly. Gong exports data; the constraint is gating and format, covered later.
Engage versus dedicated sequencers
AEs
Gong Engage
G2, Jun 2025
Contested. The 2025 complaint predates the 2026 execution-layer release.
📌 Two quotes that carry the pattern
"The additional products like forecast or engage come at an additional cost." — Scott T. Gong G2 Verified Review [2024]
"Gong Engage is awful in every single way compared to outreach. Would not recommend at all, flows are hard to get into, information is not readily available, sequencing is difficult to create and track." — Verified reviewer, "Compared to Outreach....doesn't compare" Gong G2 Verified Review [9 Jun 2025]
That second one is a 1.5-star review, and it is the harshest in the set. It is also fifteen months old and about one module, not the platform. Both facts belong in the same sentence when you quote it. If sequencing is the sticking point, the Gong versus Outreach comparison handles that head-to-head properly.
🔍 One theme, walked all the way through
Take unused breadth, because it is the theme that shows up most and gets analysed least.
The complaint is not that features are missing. It is that a team licenses a platform, uses recording and call review heavily, and never opens the rest. The bill reflects the platform. The value reflects two modules. That pattern is the core argument for revenue tech stack consolidation.
Oliv AI maintains a dated, URL-resolved vault of competitor reviews, which is how each quote here was matched back to an individual review page rather than a product listing. That method is the only reason the "still current" column above can be written honestly.
The practical implication per theme is the same shape. Pull the usage data before the renewal call, not during it. Setup and admin load is the one theme that deserves its own treatment, and it gets one later in this article.
Q4. What are reviewers actually complaining about when they complain about cost? [toc=4. Cost Complaints Decoded]
Cost complaints in Gong reviews are three different complaints wearing one label. The first is the seat price itself. The second is scope: Forecast and Engage are separately licensed, so a team can pay for a platform and still not have the module it wanted. The third, and the most common in practice, is licences bought for people who never log in. Gong publishes no figures at all, so any dollar range you read elsewhere is someone's estimate, not a price.
💰 The moment this decides
Somebody says "Gong is expensive," and the renewal conversation ends there. Everyone nods. Nobody has separated what they are actually objecting to.
I have watched that sentence kill a good tool and save a bad one in the same quarter. It is the least useful three words in a renewal room.
❌ Why treating cost complaints as damning is lazy
Every enterprise tool collects price complaints. On its own, that tells you nothing about fit. A cost complaint only becomes evidence when you can say which of the three it is.
Plot your login rate against module usage to find out which cost complaint you actually have before the renewal call.
Worth saying clearly: gong.io/pricing states that licences are per user and that a platform fee exists. It publishes no numbers. Any per-seat range you find in a comparison post is a reconstruction, not a price. Teams working through this usually need a plan to reduce sales tech stack costs before they need a new vendor.
🧮 Complaint one: the seat itself
This is the honest version, and it is the least common in the review corpus. A team uses the product widely, values it, and still finds the per-seat cost high against budget.
There is no clever answer here. Either the outcome justifies the seat or it does not, and that is a business-case question, not a review question. A revenue intelligence ROI calculation settles it faster than another round of reviews.
🧩 Complaint two: scope, not price
This one is different. The reviewer is not saying the platform costs too much. They are saying they paid for a platform and then discovered the module they wanted sits behind another line item.
"The additional products like forecast or engage come at an additional cost." — Scott T. Gong G2 Verified Review [2024]
Metering compounds this. Certain AI features draw from a shared credit pool, so what a seat includes today is not a fixed thing. That mechanic gets its own section next, and the forecasting side is unpacked in the Gong forecasting breakdown.
💸 Complaint three: seats nobody uses
This is the largest one, and it almost never appears as a price complaint. It appears as breadth going unused, which is exactly what Karel Bos described on TrustRadius in 2024.
Before you argue about cost, pull two numbers. First, seats with zero logins in the last thirty days. Second, modules licensed against modules actually opened last quarter.
The dormant-seat count moves renewals more than any feature argument I have ever made. It is also the number almost nobody pulls before the call. Full cost modelling and a quote checklist live in the Gong pricing breakdown; this page stays with what users report about the bill.
Q5. What are Gong credits, and how do they change what a seat includes? [toc=5. Credits and Metering]
Gong credits are a metered, company-wide pool that specific AI features draw from. Documentation from mid-2026 sets the mechanics: roughly ten emails to a credit, a call over ten minutes to a credit, monthly caps that do not roll over, and an API that errors at zero. Question-based AI trackers, AI Ask Anything, AI Briefer, and the MCP server consume credits. Pretrained trackers and viewing existing results do not. Gong states that existing agreements are unchanged, so this is documented metering, not a contract change.
📋 What draws from the pool, and what does not
The list is published, and it is short enough to check in one sitting.
Consumes credits:
Question-based AI trackers, which run continuously on new calls and emails
The AI Ask Anything and AI Briefer APIs
The MCP server, which is the connector that lets outside AI agents query Gong
Does not consume credits:
Pretrained trackers that ship with the product
Viewing results a tracker has already produced
Unpublishing a tracker, which stops its consumption entirely
That last point is the one most admins miss. Creation is free. Running is not.
🧮 A worked example you can check against your own console
Credit draw compounds from calls, emails, and every extra published tracker, which is why the budgeting unit is no longer the seat.
Take a 40-rep team. Say each rep sits on twelve calls a week that run past ten minutes.
At the documented rate of one credit per call over ten minutes, that is 480 credits a week for call analysis alone, before email. Email adds roughly one credit per ten messages analysed. Multiply by four weeks and you are into four figures monthly, from one published tracker set. Anyone running sales call analytics at that volume should model this before renewal.
Now add three more question-based trackers because three teams each wanted their own. The draw multiplies with them, not with your headcount.
⚠️ What happens when the pool hits zero
The monthly cap does not carry over. Unused credits expire, and the pool is shared across the whole company, not allocated per team.
At zero, the API returns an error and question-based trackers stop processing new data. Nothing breaks loudly. A tracker simply stops producing results, and the person who set it up finds out later. If you have wired Gong into other systems, check the Gong integrations that depend on that API.
I want to be precise about the framing here, because plenty of posts have got it wrong. This is published metering, documented openly by the vendor. It is not a contract breach, and Gong has said existing agreements stand.
💰 Why this changes the renewal conversation
The seat used to be the unit you budgeted. Now the unit is the seat plus a shared pool whose draw depends on how many trackers your admins published, not on how many people you hired.
That is a genuinely different budgeting problem. Headcount is predictable. Tracker sprawl is not. This is exactly the pressure that pushes teams toward reducing sales tech stack costs before the quote lands.
Oliv AI runs its agents against a persistent context graph rather than a shared credit pool that one heavy tracker can drain mid-month, so the unit a RevOps lead budgets stays the unit they signed for. That is a design choice with its own trade-offs, not a free lunch, and we say so plainly.
For the full cost model and a quote checklist, the Gong pricing breakdown carries it. This page stays with the mechanics and what users report.
Q6. Are Gong's Smart Trackers accurate, or just unlimited? [toc=6. Tracker Reality Check]
Gong's AI Tracker detects meaning rather than keywords, and Gong's own documentation says so, which retires the common claim that trackers only match phrases. The real tension is packaging. Gong Foundation advertises unlimited AI trackers, while the credit documentation makes question-based trackers the largest credit consumer and instructs admins to unpublish trackers that no longer provide value. Unlimited to create is not unlimited to run. Audit published trackers quarterly, and unpublish the ones nobody reads.
❌ The claim everyone repeats, including us
The standard line in competitor content is that Gong trackers are glorified keyword search. Miss a synonym, miss the signal.
I have made a version of that argument myself, and earlier drafts of this very page carried it. It does not survive contact with the documentation. The honest version of the critique sits in the write-up on Gong limitations and challenges.
✅ Why the claim is wrong
Gong's help documentation distinguishes between keyword trackers and AI trackers. Question-based AI trackers are described as detecting meaning, not just matching phrases.
You can argue about how well that works on your data. You cannot argue that the feature is keyword matching, because the vendor documents otherwise. Correcting that publicly costs me a talking point and buys the rest of this article some credibility.
⚠️ The narrower claim that does survive
Put the two published sources side by side and a real contradiction appears.
Gong Packaging Versus Gong Credit Documentation on AI Trackers
Source
What it says
Gong Foundation packaging
Unlimited AI Trackers included
Gong credit documentation
Question-based trackers are the biggest credit consumer, and admins should unpublish those no longer providing value
Both statements are true. Together they mean you can create as many trackers as you like, and each published one draws from a finite monthly pool. Unlimited describes creation. Metering governs operation.
⏰ What to do about it on Monday
Three steps, in order:
Export the list of published trackers and note who requested each one.
Check which ones have been opened in the last ninety days.
Unpublish the rest, which stops their credit draw immediately.
Most teams I have seen do this find that a third of their trackers were built for a launch, a competitor scare, or a QBR that happened two years ago. If the goal is methodology scoring rather than theme spotting, auto-scoring MEDDIC, BANT, and SPICED from calls is a cleaner route than tracker sprawl.
🗣️ What reviewers say about living with them
"The AI tracker's ability to identify common themes across different recordings, even those not from my department, very useful... I found the AI tracker setup to be quite difficult, especially concerning the user interface when setting up keywords or smart trackers." — Verified reviewer, "Challenging Setup with Valuable AI Tracking" Gong G2 Verified Review [3 Oct 2025]
"Good for tracking deals, account engagement overall, divided transcript and accurate AI highlights for calls." — Verified reviewer, "Compared to Outreach....doesn't compare" Gong G2 Verified Review [9 Jun 2025]
The second quote comes from a 1.5-star review. Even the harshest reviewer in this set rates the AI highlights as accurate. The complaint is configuration effort, not detection quality.
Tracker depth, including how to write a question-based tracker that earns its credits, sits in the guide to Gong Smart Trackers.
Q7. Why do reviewers rate Gong's support highly but its implementation poorly? [toc=7. Rollout vs Support]
TrustRadius reviewers score Gong's support in the 8.2 to 8.6 range, but its implementation closer to 5.7. That gap tells you where the risk sits. The tickets get answered. The configuration, tracker setup, CRM field mapping, and change management land on whoever owns the tool internally. Before signing or renewing, name a RevOps owner and budget several weeks of their time. Teams that skip this step produce the admin-load complaints that recur across the review set.
📊 What a 2.5-point gap actually means
Support and implementation are scored by the same reviewers, on the same platform, about the same product. So the gap is not sampling noise. It is a structural signal.
High support scores mean the vendor answers when you ask. Low implementation scores mean the work you have to do before you can ask is heavier than expected.
🧰 What the implementation work actually consists of
This is the itemised list that rarely makes it into a demo:
CRM field mapping, so deal data resolves against the right opportunity records
Call recording rules by team, region, and consent requirement
Tracker design, including who owns each one and who reads the output
Scorecard and coaching workflow setup for managers
Integration testing with your sequencer, calendar, and dialler
Change management with reps who did not ask to be recorded
Six workstreams. None of them are hard individually. All of them need one person who owns the whole thing. The mapping step alone usually exposes whatever CRM data quality debt the team has been carrying.
🗣️ What reviewers describe
"I found the AI tracker setup to be quite difficult, especially concerning the user interface when setting up keywords or smart trackers." — Verified reviewer, "Challenging Setup with Valuable AI Tracking" Gong G2 Verified Review [3 Oct 2025]
"Design is user friendly and ensure the elements are visible and with no confusion... Real Time integrations can be time consuming." — Verified reviewer, "User-Friendly Design, but Real-Time Integrations Take Too Long" Gong G2 Verified Review [21 Apr 2026]
Note the second date. April 2026, not 2024. The interface gets praised, and the integration time still gets flagged. That is a complaint that has survived recent releases, which is exactly the test this article applies. The Gong CRM integration path is where most of that time goes.
✅ The pre-signature readiness checklist
Reviewers rate support highly and implementation poorly, so these five steps belong in the project plan before the contract is signed.
Run these five before the contract, not after:
Name the internal owner by first name, in writing, in the business case.
Block their calendar for the rollout weeks and tell their manager.
Confirm your CRM object model is clean enough for deal-level mapping.
Agree the first two workflows you will run, and ignore the rest at launch.
Set a go-live date that assumes integration testing takes longer than quoted.
Time-to-value is an owner problem before it is a product problem. Name the human before you sign the paper.
Q8. Which teams get value from Gong, reps, managers or post-sale? [toc=8. Role-by-Role Value]
Managers and RevOps leads review Gong for visibility, coaching scale, and deal boards, and they rate it highly. Individual contributors more often describe notification volume, constant recording, and CRM work the tool relocated rather than removed. Post-sale teams can use Gong, which ships customer success capability and an execution layer, but the review corpus is thin there and the recurring theme is breadth going unused. Licence for the two workflows you will actually run, not for the ones you intend to run later.
👥 Two people, one dashboard, Monday morning
A sales manager opens Gong on Monday and sees a coaching queue. Calls scored, deals flagged, a rep who has not asked a pricing question in three weeks.
An AE on the same team opens the same tool and sees a list of things that were recorded about them. Same platform. Very different feeling. That split is why coaching at scale using AI lands differently by role.
❌ Why top-down seat buying breaks this
The standard rollout buys seats for the whole org because the licence is cheaper in bulk. Adoption is assumed to follow.
It usually does not. Managers adopt fast because the product solves their visibility problem directly. Reps adopt slower, because the value to them is indirect and the cost to them is immediate.
By renewal, you have two populations on one line item, and the average usage number hides both.
✅ What changed, and what to measure now
Usage telemetry has got good enough that you can answer this per person. Pull logins by role for the last thirty days and split the list.
Look at three numbers:
Weekly active managers as a share of manager seats
Weekly active reps as a share of rep seats
Modules opened per role, not per company
If manager adoption is high and rep adoption is low, the tool is working as designed and your seat count is wrong. Those are different problems, and only one of them is Gong's. Tracking them properly is a revenue performance analytics exercise, not a procurement one.
🧩 The post-sale question, answered accurately
Gong is not sales-only. It ships customer success capability, and in June 2026 it launched the Revenue Harness execution layer alongside Gong Enable.
So the honest answer for CS teams is yes, with conditions. The review corpus is genuinely thin for post-sale users, which means you have less peer evidence to lean on. Decide the two CS workflows you will run before you licence anyone, because breadth going unused is the single most repeated theme in this entire review set. Teams weighing this against dedicated tooling should read the comparison of customer success platforms.
"Gong Engage is awful in every single way compared to outreach... flows are hard to get into, information is not readily available, sequencing is difficult to create and track." — Verified reviewer, "Compared to Outreach....doesn't compare" Gong G2 Verified Review [9 Jun 2025]
That second review is a rep's view of a module reps live inside daily. It predates the 2026 execution-layer release, so date it when you quote it. The module itself is unpacked in the explainer on what Gong Engage does.
The failure mode underneath all of this is seats bought for a future state that never arrives. It is the largest recoverable line item in most bloated renewals, and almost nobody audits it until the quote lands.
Q9. Can you get your data out of Gong, and who has to consent to the recording? [toc=9. Data Exit and Consent]
Gong exports data. The accurate limitation is narrower: its MCP server exposes three tools and returns a synthesized answer rather than raw activity data, so an agent querying Gong gets a conclusion, not the rows. Reviewers separately describe bulk snippet download gated behind a plan level. On consent, the EU AI Act's disclosure duty applies from 2 August 2026, and Germany, Austria, and Greece require all-party consent, so a global rollout needs per-country recording settings, not one default.
❌ The myth worth killing first
Plenty of competitor pages claim Gong locks your data in. That claim is contradicted by Gong's own published pages, and repeating it costs you credibility in a procurement conversation.
Gong has export paths. The real questions are about format, gating, and what an AI agent receives when it asks. The security and processing terms are unpacked separately in the note on Gong DPA and security.
🔌 What the MCP server actually returns
MCP stands for Model Context Protocol, the standard that lets outside AI tools query a system directly.
Gong's MCP server exposes three tools and returns a synthesized answer. That means an agent asking about an account gets Gong's conclusion, not the underlying call rows, email records, or activity timestamps.
If you are building your own agent layer on top of your stack, this matters a lot. You can consume Gong's judgment. You cannot easily rebuild it somewhere else. That constraint is the crux of any build versus buy decision on revenue AI.
🗣️ What a reviewer experienced
"I cannot download all the data myself unless we upgrade the plan, which isn't ideal and results in me not fully utilizing Gong. The requirement to download snippets one by one using copy and paste is particularly annoying." — Verified reviewer, "Challenging Setup with Valuable AI Tracking" Gong G2 Verified Review [3 Oct 2025]
"Real Time integrations can be time consuming." — Verified reviewer, "User-Friendly Design, but Real-Time Integrations Take Too Long" Gong G2 Verified Review [21 Apr 2026]
That first quote is a 3-star review from a user who likes the product. It is not a data-lock-in accusation. It is a plan-tier constraint, which is a different thing and easier to solve in a contract. Teams that do decide to move should read the migration from Gong walkthrough first.
⚠️ The consent map nobody puts in a review post
Recording rules are not uniform, and one global default will get you in trouble.
Recording and Disclosure Requirements by Jurisdiction (2026)
Requirement
Where it applies
What it means for rollout
EU AI Act Article 50 disclosure
EU, from 2 August 2026
People must be told they are interacting with AI
All-party consent
Germany, Austria, Greece, and others
Every participant must agree, not just the host
GDPR Article 9
EU
Voiceprints count as biometric data, with stricter handling
Configure recording and disclosure by country, not by org default. If your team sells into Europe, this is a rollout task, not a legal footnote. The wider governance checklist sits in the guide to AI CRM trust and governance for RevOps.
✅ Three things to do before you sign
Run one full export during the evaluation period, and check the format you actually receive.
Write export format, cadence, and destination into the contract, not the email thread.
Audit recording and disclosure settings per country before your first EU quarter.
Test the export while you are happy. Nobody discovers a portability problem on a good day.
Q10. Should you renew Gong, and how do you prove it paid for itself? [toc=10. Renew, Renegotiate or Replace]
Renew if more than half your licensed users log in weekly, managers run structured call reviews on a cadence, and you use at least two modules beyond recording. In that configuration the price is defensible. Renegotiate before you replace if seats are dormant or the credit pool drains on trackers nobody reads. Prove payback with one outcome metric, such as win rate or cycle-time delta, not calls recorded. LinkedIn's 2026 buyer research and Salesforce's State of Sales both point the same way: measure outcomes, and fix CRM data quality first.
💰 The room this decision happens in
The quote lands. Somebody has already forwarded it to finance. A VP says the number out loud and the room goes quiet.
Nobody in that room has pulled the usage export yet. That is almost always true, and it is why these calls go badly.
❌ Why the obvious move is the wrong one
The reflex is an across-the-board seat cut. Trim twenty percent, save the number, move on.
That breaks the thing that was working. Manager adoption is usually high, because coaching queues and deal boards solve their problem directly. Cut evenly and you damage the coaching cadence while leaving the dormant rep seats untouched. If coaching is the value you are protecting, compare it against dedicated sales coaching software before you cut.
✅ The three metrics that settle it
Pull these before the call, not during it:
Weekly active users as a share of licensed seats, split by role
Modules licensed against modules actually opened last quarter
Credit draw by tracker, with the owner's name beside each one
Then apply the rule:
Renew, Renegotiate, or Replace: The Decision Rule
Situation
Decision
Over half log in weekly, two or more modules in use
Renew
High manager use, low rep use, dormant seats
Renegotiate seat count and mix
Low use across roles, credits draining on unread trackers
Evaluate alternatives, but finish the audit first
⏰ The renegotiation checklist
Bring the dormant-seat count as a number, not an impression.
Ask which modules can be dropped and re-added later.
Ask what happens to your credit pool if tracker count falls.
Get renewal uplift terms in writing before you discuss anything else.
⭐ How to prove payback
Adoption is not payback. Calls recorded is not payback. Pick one outcome metric and hold it for two quarters. The mechanics of that sit in the revenue intelligence ROI calculator.
LinkedIn's 2026 buyer research, run with Ipsos across 900-plus B2B buyers, argues for measuring AI by deals progressed rather than activity logged. Salesforce's 2026 State of Sales, covering 4,000-plus sellers, names data quality and admin friction as the top blockers to AI returns. Both point at the same fix: clean the CRM before you expand seats, which is a CRM data strategy problem more than a tooling one.
"The additional products like forecast or engage come at an additional cost." — Scott T. Gong G2 Verified Review [2024]
One honest concession before you act on any of this. The alternatives are not equivalents. If your team is getting real value mid-contract, renegotiate rather than replace, and anchor the decision to your renewal event rather than a calendar month.
Q11. If the complaints are about scope and cost, what does a modular alternative look like? [toc=11. The Modular Alternative]
The recurring criticisms in Gong's review corpus are about scope and cost per outcome, not capability, which points toward modularity rather than replacement. Oliv AI is built as an agentic revenue layer that can sit on top of Gong rather than displace it, so a team mid-contract can add agent-run workflows without unwinding a platform that already works. Oliv AI has no public review corpus of its own, which on a page about reviews is worth stating plainly. Named customers include Sprinto and Triple Whale.
🧭 What eleven sections of review reading actually pointed at
Not accuracy. Not reliability. Not transcription quality.
Scope, cost per outcome, and rollout effort. Every recurring theme in this article traces back to one of those three. That is a shape of problem, and it has a shape of answer.
❌ Why the rip-and-replace pitch fails right now
You are reading this mid-renewal, with a quote open. A vendor telling you to migrate an entire platform is asking you to take on a second project while you are trying to close a first one.
I have made that pitch before and watched it die on the call. It deserved to. The switching cost lands on the same RevOps lead who is already carrying the rollout debt. A straight feature comparison is available in Gong versus Oliv for anyone who does want it.
✅ What changes when work is agent-run instead of app-run
First-generation revenue intelligence surfaces information and leaves the work to a person. Somebody still opens the dashboard, reads the deal board, and updates the record.
Agent-run work inverts that. The system holds context across accounts and opportunities, then executes a defined workflow against it. The person reviews output instead of assembling it. That shift is traced in more depth in the piece on AI agents versus SaaS dashboards.
That distinction is the whole argument, and it is worth being sceptical about. Plenty of vendors say agent and mean automation with a nicer label.
🧩 Where Oliv AI actually sits
Oliv AI runs agents against a continuously updated context graph of accounts and opportunities, drawing on the call and CRM data a team already has, which means it can add orchestration on top of a live Gong deployment rather than requiring a migration first. We think that posture is more useful to a reader mid-renewal than a displacement pitch, and it is checkable rather than aspirational.
Sprinto and Triple Whale use it daily. Oliv AI is SOC 2 Type II certified, GDPR and CCPA compliant, with an open export policy, and the trust documentation is public at trust.oliv.ai. The agent set itself is documented in Oliv AI agents for sales teams.
⚠️ What this page will not claim
Three disclosures, because a page about honest review reading has to hold itself to the same rule.
Oliv AI has no G2 review corpus to set against Gong's 6,694 reviews. That is a real gap, and it is not hidden here.
No price appears in this article, because the figure needs confirming before publication.
No savings number, no migration promise, and no rating. None of those are currently sourceable to a published document.
Oliv AI is also wrong for some buyers. If you want call recording alone, or you run a B2C support team, the category fit is poor and you should say so internally before anyone books a demo.
If you are sitting with a Gong quote and a usage export, that is exactly the conversation worth having. Tell us what your dormant-seat number looks like, and we will tell you honestly whether an agent layer helps. More detail on the RevOps side sits at Oliv for RevOps, and if it is useful, book a walkthrough.
Q1. What do Gong reviews actually say in 2026? [toc=1. The 2026 Verdict]
Gong reviews in 2026 are strongly positive. Gong holds 4.7 out of 5 across roughly 6,694 G2 reviews, 9.1 out of 10 on TrustRadius across more than 1,000 ratings, 4.8 on Capterra, and 4.7 across verified Gartner Peer Insights reviews. Gartner also named Gong a Leader in its 2025 Magic Quadrant for Revenue Action Orchestration. The recurring criticisms are not about accuracy or reliability. They cluster on scope, cost per outcome, and rollout effort. Read them as feedback from people who broadly like the product.
📊 How this review set was read
Most Gong review round-ups never tell you how the quotes were picked. So here is the method first, before any finding.
Four platforms were read: G2, TrustRadius, Capterra, and Gartner Peer Insights. Only reviews that resolve to an individual review URL with a visible date were kept in the analysed subset. Product pages and unlinked quotes were excluded. The population rating is reported separately from that subset, and the two are never mixed.
That distinction matters more than it sounds. A platform average describes thousands of users. A quote describes one person on one day. The same discipline applies when you compare any revenue intelligence platform on peer-review evidence alone.
⭐ The ratings, reconciled in one place
Gong Ratings Across Four Review Platforms (2026)
Platform
Score
Volume
What it tells you
G2
4.7 / 5
~6,694 reviews
Broadest sample, heaviest on mid-market sellers
TrustRadius
9.1 / 10
1,090+ ratings
Deeper written detail, feature-level scoring
Capterra
4.8 / 5
561 reviews
Skews smaller companies
Gartner Peer Insights
4.7 / 5
~371 reviews
Identity-verified, enterprise-weighted
The four platforms agree. That agreement is the finding. When a product scores this consistently across different sampling methods, the quality question is answered, and the remaining questions are about fit and cost.
One number inside TrustRadius is worth pulling out early. Reviewers score Gong's support in the 8.2 to 8.6 range, but its implementation closer to 5.7. The helpdesk is not the weak point. The rollout is, which is why the Gong implementation timeline matters more than most buyers expect.
⚠️ What a single review can and cannot prove
A review proves that one person had one experience, on one date, on one module. Nothing more. It cannot establish how common something is, and it cannot tell you what a vendor charges.
That rule is why this article dates every quote in the body text. Review sites stack five years of releases on one page, so a 2024 complaint about a module Gong has since rebuilt sits beside a 2026 one and looks identical. Reading the current Gong feature set beside an older review is the only way to tell them apart.
"Design is user friendly and ensure the elements are visible and with no confusion... Real Time integrations can be time consuming." — Verified reviewer, "User-Friendly Design, but Real-Time Integrations Take Too Long" Gong G2 Verified Review [21 Apr 2026]
Those two sit at opposite ends of the same story. The product works. The question is how much of it you are actually going to use.
Q2. Why does a 4.7 rating make the complaints more useful, not less? [toc=2. How to Read the Reviews]
When a product averages 4.7, the criticisms that still recur are the ones people who like the tool cannot ignore. That makes them structural, not incidental. The limitation is real and worth stating plainly: buyers who evaluated Gong and chose something else never wrote a review, so the corpus describes users, not the market. Treat every theme as a hypothesis, date it, then check it against Gong's current documentation before you act on it at renewal.
🧾 The scene most readers are actually in
You have a renewal quote open in one tab and six thousand reviews in another. You are not deciding whether conversation intelligence is useful. You decided that two years ago.
You are deciding whether this specific bill is justified, and whether the complaints you are reading are about the product or about the price. Those are different problems with different answers, and the split between revenue intelligence and conversation intelligence is usually where it starts.
❌ Why the normal way of reading reviews fails
The default move is to sort by lowest rating and read the angry ones. It feels efficient. It is close to useless.
Review platforms present a five-year archive as if it were a snapshot. A complaint about a module that shipped in 2023 renders exactly like one written last month. Nothing on the page tells you which criticisms have survived two years of releases.
The reading method behind this article: date every quote, then check it against current documentation before acting on it.
✅ The rule this article follows
Every quote here carries its date in the body text, not in a footnote. Every theme is checked against Gong's current published documentation before it is presented as a live issue.
Where a criticism still stands, the current documentation appears beside it. Where the product has moved on, that is said outright. This is slower to write and much harder to argue with. The same test applies to the known Gong limitations that competitors quote most often.
⚠️ The concession you should hold onto
Here is the uncomfortable part, and it is worth saying before any analysis. For a team using Gong broadly, with managers running structured call reviews and two or more modules in daily use, the price is defensible. If that describes you, stop reading and renew.
A satisfied-customer review set is genuinely a poor guide for a prospective buyer. I could be reading this too strongly, but I think the survivorship gap is the single biggest flaw in every "we analysed X reviews" article on this topic, including earlier versions of this one.
"I appreciate how Gong organizes all our chats, videos, and audio with clients into a single source... I found the AI tracker setup to be quite difficult." — Verified reviewer, "Challenging Setup with Valuable AI Tracking" Gong G2 Verified Review [3 Oct 2025]
One reviewer, two verdicts, same paragraph. That is what a 4.7 corpus actually looks like up close.
Q3. What do reviewers complain about most, and does each complaint still hold? [toc=3. Recurring Complaints]
Five themes recur across verified Gong reviews: what the seat now includes; unused breadth, where teams pay for modules nobody opens; add-on cost for Forecast and Engage; setup and admin load; and notification volume. Accuracy and transcription quality are rarely the objection. Every theme needs a date check, because several criticised modules have since been rebuilt, and a 2024 review is evidence about 2024 only.
🗂️ The five themes, with a current-state check
Recurring Gong Complaint Themes and Whether They Still Hold in 2026
Theme
Who raises it
Module
Evidence
Still current in 2026?
Unused breadth
Admins, RevOps
Platform-wide
Karel Bos, TrustRadius, 2024
Yes. Gong has added the Revenue Harness execution layer and Gong Enable, so scope has widened, not narrowed.
Add-on cost for modules
Buyers, managers
Forecast, Engage
Scott T., G2, 2024
Yes. Forecast and Engage remain separately licensed.
Setup and admin load
Admins
AI Trackers, integrations
G2, Oct 2025 and Apr 2026
Yes. TrustRadius scores implementation near 5.7 against support near 8.6.
Export and data access
Analysts, RevOps
Snippets, API
G2, Oct 2025
Partly. Gong exports data; the constraint is gating and format, covered later.
Engage versus dedicated sequencers
AEs
Gong Engage
G2, Jun 2025
Contested. The 2025 complaint predates the 2026 execution-layer release.
📌 Two quotes that carry the pattern
"The additional products like forecast or engage come at an additional cost." — Scott T. Gong G2 Verified Review [2024]
"Gong Engage is awful in every single way compared to outreach. Would not recommend at all, flows are hard to get into, information is not readily available, sequencing is difficult to create and track." — Verified reviewer, "Compared to Outreach....doesn't compare" Gong G2 Verified Review [9 Jun 2025]
That second one is a 1.5-star review, and it is the harshest in the set. It is also fifteen months old and about one module, not the platform. Both facts belong in the same sentence when you quote it. If sequencing is the sticking point, the Gong versus Outreach comparison handles that head-to-head properly.
🔍 One theme, walked all the way through
Take unused breadth, because it is the theme that shows up most and gets analysed least.
The complaint is not that features are missing. It is that a team licenses a platform, uses recording and call review heavily, and never opens the rest. The bill reflects the platform. The value reflects two modules. That pattern is the core argument for revenue tech stack consolidation.
Oliv AI maintains a dated, URL-resolved vault of competitor reviews, which is how each quote here was matched back to an individual review page rather than a product listing. That method is the only reason the "still current" column above can be written honestly.
The practical implication per theme is the same shape. Pull the usage data before the renewal call, not during it. Setup and admin load is the one theme that deserves its own treatment, and it gets one later in this article.
Q4. What are reviewers actually complaining about when they complain about cost? [toc=4. Cost Complaints Decoded]
Cost complaints in Gong reviews are three different complaints wearing one label. The first is the seat price itself. The second is scope: Forecast and Engage are separately licensed, so a team can pay for a platform and still not have the module it wanted. The third, and the most common in practice, is licences bought for people who never log in. Gong publishes no figures at all, so any dollar range you read elsewhere is someone's estimate, not a price.
💰 The moment this decides
Somebody says "Gong is expensive," and the renewal conversation ends there. Everyone nods. Nobody has separated what they are actually objecting to.
I have watched that sentence kill a good tool and save a bad one in the same quarter. It is the least useful three words in a renewal room.
❌ Why treating cost complaints as damning is lazy
Every enterprise tool collects price complaints. On its own, that tells you nothing about fit. A cost complaint only becomes evidence when you can say which of the three it is.
Plot your login rate against module usage to find out which cost complaint you actually have before the renewal call.
Worth saying clearly: gong.io/pricing states that licences are per user and that a platform fee exists. It publishes no numbers. Any per-seat range you find in a comparison post is a reconstruction, not a price. Teams working through this usually need a plan to reduce sales tech stack costs before they need a new vendor.
🧮 Complaint one: the seat itself
This is the honest version, and it is the least common in the review corpus. A team uses the product widely, values it, and still finds the per-seat cost high against budget.
There is no clever answer here. Either the outcome justifies the seat or it does not, and that is a business-case question, not a review question. A revenue intelligence ROI calculation settles it faster than another round of reviews.
🧩 Complaint two: scope, not price
This one is different. The reviewer is not saying the platform costs too much. They are saying they paid for a platform and then discovered the module they wanted sits behind another line item.
"The additional products like forecast or engage come at an additional cost." — Scott T. Gong G2 Verified Review [2024]
Metering compounds this. Certain AI features draw from a shared credit pool, so what a seat includes today is not a fixed thing. That mechanic gets its own section next, and the forecasting side is unpacked in the Gong forecasting breakdown.
💸 Complaint three: seats nobody uses
This is the largest one, and it almost never appears as a price complaint. It appears as breadth going unused, which is exactly what Karel Bos described on TrustRadius in 2024.
Before you argue about cost, pull two numbers. First, seats with zero logins in the last thirty days. Second, modules licensed against modules actually opened last quarter.
The dormant-seat count moves renewals more than any feature argument I have ever made. It is also the number almost nobody pulls before the call. Full cost modelling and a quote checklist live in the Gong pricing breakdown; this page stays with what users report about the bill.
Q5. What are Gong credits, and how do they change what a seat includes? [toc=5. Credits and Metering]
Gong credits are a metered, company-wide pool that specific AI features draw from. Documentation from mid-2026 sets the mechanics: roughly ten emails to a credit, a call over ten minutes to a credit, monthly caps that do not roll over, and an API that errors at zero. Question-based AI trackers, AI Ask Anything, AI Briefer, and the MCP server consume credits. Pretrained trackers and viewing existing results do not. Gong states that existing agreements are unchanged, so this is documented metering, not a contract change.
📋 What draws from the pool, and what does not
The list is published, and it is short enough to check in one sitting.
Consumes credits:
Question-based AI trackers, which run continuously on new calls and emails
The AI Ask Anything and AI Briefer APIs
The MCP server, which is the connector that lets outside AI agents query Gong
Does not consume credits:
Pretrained trackers that ship with the product
Viewing results a tracker has already produced
Unpublishing a tracker, which stops its consumption entirely
That last point is the one most admins miss. Creation is free. Running is not.
🧮 A worked example you can check against your own console
Credit draw compounds from calls, emails, and every extra published tracker, which is why the budgeting unit is no longer the seat.
Take a 40-rep team. Say each rep sits on twelve calls a week that run past ten minutes.
At the documented rate of one credit per call over ten minutes, that is 480 credits a week for call analysis alone, before email. Email adds roughly one credit per ten messages analysed. Multiply by four weeks and you are into four figures monthly, from one published tracker set. Anyone running sales call analytics at that volume should model this before renewal.
Now add three more question-based trackers because three teams each wanted their own. The draw multiplies with them, not with your headcount.
⚠️ What happens when the pool hits zero
The monthly cap does not carry over. Unused credits expire, and the pool is shared across the whole company, not allocated per team.
At zero, the API returns an error and question-based trackers stop processing new data. Nothing breaks loudly. A tracker simply stops producing results, and the person who set it up finds out later. If you have wired Gong into other systems, check the Gong integrations that depend on that API.
I want to be precise about the framing here, because plenty of posts have got it wrong. This is published metering, documented openly by the vendor. It is not a contract breach, and Gong has said existing agreements stand.
💰 Why this changes the renewal conversation
The seat used to be the unit you budgeted. Now the unit is the seat plus a shared pool whose draw depends on how many trackers your admins published, not on how many people you hired.
That is a genuinely different budgeting problem. Headcount is predictable. Tracker sprawl is not. This is exactly the pressure that pushes teams toward reducing sales tech stack costs before the quote lands.
Oliv AI runs its agents against a persistent context graph rather than a shared credit pool that one heavy tracker can drain mid-month, so the unit a RevOps lead budgets stays the unit they signed for. That is a design choice with its own trade-offs, not a free lunch, and we say so plainly.
For the full cost model and a quote checklist, the Gong pricing breakdown carries it. This page stays with the mechanics and what users report.
Q6. Are Gong's Smart Trackers accurate, or just unlimited? [toc=6. Tracker Reality Check]
Gong's AI Tracker detects meaning rather than keywords, and Gong's own documentation says so, which retires the common claim that trackers only match phrases. The real tension is packaging. Gong Foundation advertises unlimited AI trackers, while the credit documentation makes question-based trackers the largest credit consumer and instructs admins to unpublish trackers that no longer provide value. Unlimited to create is not unlimited to run. Audit published trackers quarterly, and unpublish the ones nobody reads.
❌ The claim everyone repeats, including us
The standard line in competitor content is that Gong trackers are glorified keyword search. Miss a synonym, miss the signal.
I have made a version of that argument myself, and earlier drafts of this very page carried it. It does not survive contact with the documentation. The honest version of the critique sits in the write-up on Gong limitations and challenges.
✅ Why the claim is wrong
Gong's help documentation distinguishes between keyword trackers and AI trackers. Question-based AI trackers are described as detecting meaning, not just matching phrases.
You can argue about how well that works on your data. You cannot argue that the feature is keyword matching, because the vendor documents otherwise. Correcting that publicly costs me a talking point and buys the rest of this article some credibility.
⚠️ The narrower claim that does survive
Put the two published sources side by side and a real contradiction appears.
Gong Packaging Versus Gong Credit Documentation on AI Trackers
Source
What it says
Gong Foundation packaging
Unlimited AI Trackers included
Gong credit documentation
Question-based trackers are the biggest credit consumer, and admins should unpublish those no longer providing value
Both statements are true. Together they mean you can create as many trackers as you like, and each published one draws from a finite monthly pool. Unlimited describes creation. Metering governs operation.
⏰ What to do about it on Monday
Three steps, in order:
Export the list of published trackers and note who requested each one.
Check which ones have been opened in the last ninety days.
Unpublish the rest, which stops their credit draw immediately.
Most teams I have seen do this find that a third of their trackers were built for a launch, a competitor scare, or a QBR that happened two years ago. If the goal is methodology scoring rather than theme spotting, auto-scoring MEDDIC, BANT, and SPICED from calls is a cleaner route than tracker sprawl.
🗣️ What reviewers say about living with them
"The AI tracker's ability to identify common themes across different recordings, even those not from my department, very useful... I found the AI tracker setup to be quite difficult, especially concerning the user interface when setting up keywords or smart trackers." — Verified reviewer, "Challenging Setup with Valuable AI Tracking" Gong G2 Verified Review [3 Oct 2025]
"Good for tracking deals, account engagement overall, divided transcript and accurate AI highlights for calls." — Verified reviewer, "Compared to Outreach....doesn't compare" Gong G2 Verified Review [9 Jun 2025]
The second quote comes from a 1.5-star review. Even the harshest reviewer in this set rates the AI highlights as accurate. The complaint is configuration effort, not detection quality.
Tracker depth, including how to write a question-based tracker that earns its credits, sits in the guide to Gong Smart Trackers.
Q7. Why do reviewers rate Gong's support highly but its implementation poorly? [toc=7. Rollout vs Support]
TrustRadius reviewers score Gong's support in the 8.2 to 8.6 range, but its implementation closer to 5.7. That gap tells you where the risk sits. The tickets get answered. The configuration, tracker setup, CRM field mapping, and change management land on whoever owns the tool internally. Before signing or renewing, name a RevOps owner and budget several weeks of their time. Teams that skip this step produce the admin-load complaints that recur across the review set.
📊 What a 2.5-point gap actually means
Support and implementation are scored by the same reviewers, on the same platform, about the same product. So the gap is not sampling noise. It is a structural signal.
High support scores mean the vendor answers when you ask. Low implementation scores mean the work you have to do before you can ask is heavier than expected.
🧰 What the implementation work actually consists of
This is the itemised list that rarely makes it into a demo:
CRM field mapping, so deal data resolves against the right opportunity records
Call recording rules by team, region, and consent requirement
Tracker design, including who owns each one and who reads the output
Scorecard and coaching workflow setup for managers
Integration testing with your sequencer, calendar, and dialler
Change management with reps who did not ask to be recorded
Six workstreams. None of them are hard individually. All of them need one person who owns the whole thing. The mapping step alone usually exposes whatever CRM data quality debt the team has been carrying.
🗣️ What reviewers describe
"I found the AI tracker setup to be quite difficult, especially concerning the user interface when setting up keywords or smart trackers." — Verified reviewer, "Challenging Setup with Valuable AI Tracking" Gong G2 Verified Review [3 Oct 2025]
"Design is user friendly and ensure the elements are visible and with no confusion... Real Time integrations can be time consuming." — Verified reviewer, "User-Friendly Design, but Real-Time Integrations Take Too Long" Gong G2 Verified Review [21 Apr 2026]
Note the second date. April 2026, not 2024. The interface gets praised, and the integration time still gets flagged. That is a complaint that has survived recent releases, which is exactly the test this article applies. The Gong CRM integration path is where most of that time goes.
✅ The pre-signature readiness checklist
Reviewers rate support highly and implementation poorly, so these five steps belong in the project plan before the contract is signed.
Run these five before the contract, not after:
Name the internal owner by first name, in writing, in the business case.
Block their calendar for the rollout weeks and tell their manager.
Confirm your CRM object model is clean enough for deal-level mapping.
Agree the first two workflows you will run, and ignore the rest at launch.
Set a go-live date that assumes integration testing takes longer than quoted.
Time-to-value is an owner problem before it is a product problem. Name the human before you sign the paper.
Q8. Which teams get value from Gong, reps, managers or post-sale? [toc=8. Role-by-Role Value]
Managers and RevOps leads review Gong for visibility, coaching scale, and deal boards, and they rate it highly. Individual contributors more often describe notification volume, constant recording, and CRM work the tool relocated rather than removed. Post-sale teams can use Gong, which ships customer success capability and an execution layer, but the review corpus is thin there and the recurring theme is breadth going unused. Licence for the two workflows you will actually run, not for the ones you intend to run later.
👥 Two people, one dashboard, Monday morning
A sales manager opens Gong on Monday and sees a coaching queue. Calls scored, deals flagged, a rep who has not asked a pricing question in three weeks.
An AE on the same team opens the same tool and sees a list of things that were recorded about them. Same platform. Very different feeling. That split is why coaching at scale using AI lands differently by role.
❌ Why top-down seat buying breaks this
The standard rollout buys seats for the whole org because the licence is cheaper in bulk. Adoption is assumed to follow.
It usually does not. Managers adopt fast because the product solves their visibility problem directly. Reps adopt slower, because the value to them is indirect and the cost to them is immediate.
By renewal, you have two populations on one line item, and the average usage number hides both.
✅ What changed, and what to measure now
Usage telemetry has got good enough that you can answer this per person. Pull logins by role for the last thirty days and split the list.
Look at three numbers:
Weekly active managers as a share of manager seats
Weekly active reps as a share of rep seats
Modules opened per role, not per company
If manager adoption is high and rep adoption is low, the tool is working as designed and your seat count is wrong. Those are different problems, and only one of them is Gong's. Tracking them properly is a revenue performance analytics exercise, not a procurement one.
🧩 The post-sale question, answered accurately
Gong is not sales-only. It ships customer success capability, and in June 2026 it launched the Revenue Harness execution layer alongside Gong Enable.
So the honest answer for CS teams is yes, with conditions. The review corpus is genuinely thin for post-sale users, which means you have less peer evidence to lean on. Decide the two CS workflows you will run before you licence anyone, because breadth going unused is the single most repeated theme in this entire review set. Teams weighing this against dedicated tooling should read the comparison of customer success platforms.
"Gong Engage is awful in every single way compared to outreach... flows are hard to get into, information is not readily available, sequencing is difficult to create and track." — Verified reviewer, "Compared to Outreach....doesn't compare" Gong G2 Verified Review [9 Jun 2025]
That second review is a rep's view of a module reps live inside daily. It predates the 2026 execution-layer release, so date it when you quote it. The module itself is unpacked in the explainer on what Gong Engage does.
The failure mode underneath all of this is seats bought for a future state that never arrives. It is the largest recoverable line item in most bloated renewals, and almost nobody audits it until the quote lands.
Q9. Can you get your data out of Gong, and who has to consent to the recording? [toc=9. Data Exit and Consent]
Gong exports data. The accurate limitation is narrower: its MCP server exposes three tools and returns a synthesized answer rather than raw activity data, so an agent querying Gong gets a conclusion, not the rows. Reviewers separately describe bulk snippet download gated behind a plan level. On consent, the EU AI Act's disclosure duty applies from 2 August 2026, and Germany, Austria, and Greece require all-party consent, so a global rollout needs per-country recording settings, not one default.
❌ The myth worth killing first
Plenty of competitor pages claim Gong locks your data in. That claim is contradicted by Gong's own published pages, and repeating it costs you credibility in a procurement conversation.
Gong has export paths. The real questions are about format, gating, and what an AI agent receives when it asks. The security and processing terms are unpacked separately in the note on Gong DPA and security.
🔌 What the MCP server actually returns
MCP stands for Model Context Protocol, the standard that lets outside AI tools query a system directly.
Gong's MCP server exposes three tools and returns a synthesized answer. That means an agent asking about an account gets Gong's conclusion, not the underlying call rows, email records, or activity timestamps.
If you are building your own agent layer on top of your stack, this matters a lot. You can consume Gong's judgment. You cannot easily rebuild it somewhere else. That constraint is the crux of any build versus buy decision on revenue AI.
🗣️ What a reviewer experienced
"I cannot download all the data myself unless we upgrade the plan, which isn't ideal and results in me not fully utilizing Gong. The requirement to download snippets one by one using copy and paste is particularly annoying." — Verified reviewer, "Challenging Setup with Valuable AI Tracking" Gong G2 Verified Review [3 Oct 2025]
"Real Time integrations can be time consuming." — Verified reviewer, "User-Friendly Design, but Real-Time Integrations Take Too Long" Gong G2 Verified Review [21 Apr 2026]
That first quote is a 3-star review from a user who likes the product. It is not a data-lock-in accusation. It is a plan-tier constraint, which is a different thing and easier to solve in a contract. Teams that do decide to move should read the migration from Gong walkthrough first.
⚠️ The consent map nobody puts in a review post
Recording rules are not uniform, and one global default will get you in trouble.
Recording and Disclosure Requirements by Jurisdiction (2026)
Requirement
Where it applies
What it means for rollout
EU AI Act Article 50 disclosure
EU, from 2 August 2026
People must be told they are interacting with AI
All-party consent
Germany, Austria, Greece, and others
Every participant must agree, not just the host
GDPR Article 9
EU
Voiceprints count as biometric data, with stricter handling
Configure recording and disclosure by country, not by org default. If your team sells into Europe, this is a rollout task, not a legal footnote. The wider governance checklist sits in the guide to AI CRM trust and governance for RevOps.
✅ Three things to do before you sign
Run one full export during the evaluation period, and check the format you actually receive.
Write export format, cadence, and destination into the contract, not the email thread.
Audit recording and disclosure settings per country before your first EU quarter.
Test the export while you are happy. Nobody discovers a portability problem on a good day.
Q10. Should you renew Gong, and how do you prove it paid for itself? [toc=10. Renew, Renegotiate or Replace]
Renew if more than half your licensed users log in weekly, managers run structured call reviews on a cadence, and you use at least two modules beyond recording. In that configuration the price is defensible. Renegotiate before you replace if seats are dormant or the credit pool drains on trackers nobody reads. Prove payback with one outcome metric, such as win rate or cycle-time delta, not calls recorded. LinkedIn's 2026 buyer research and Salesforce's State of Sales both point the same way: measure outcomes, and fix CRM data quality first.
💰 The room this decision happens in
The quote lands. Somebody has already forwarded it to finance. A VP says the number out loud and the room goes quiet.
Nobody in that room has pulled the usage export yet. That is almost always true, and it is why these calls go badly.
❌ Why the obvious move is the wrong one
The reflex is an across-the-board seat cut. Trim twenty percent, save the number, move on.
That breaks the thing that was working. Manager adoption is usually high, because coaching queues and deal boards solve their problem directly. Cut evenly and you damage the coaching cadence while leaving the dormant rep seats untouched. If coaching is the value you are protecting, compare it against dedicated sales coaching software before you cut.
✅ The three metrics that settle it
Pull these before the call, not during it:
Weekly active users as a share of licensed seats, split by role
Modules licensed against modules actually opened last quarter
Credit draw by tracker, with the owner's name beside each one
Then apply the rule:
Renew, Renegotiate, or Replace: The Decision Rule
Situation
Decision
Over half log in weekly, two or more modules in use
Renew
High manager use, low rep use, dormant seats
Renegotiate seat count and mix
Low use across roles, credits draining on unread trackers
Evaluate alternatives, but finish the audit first
⏰ The renegotiation checklist
Bring the dormant-seat count as a number, not an impression.
Ask which modules can be dropped and re-added later.
Ask what happens to your credit pool if tracker count falls.
Get renewal uplift terms in writing before you discuss anything else.
⭐ How to prove payback
Adoption is not payback. Calls recorded is not payback. Pick one outcome metric and hold it for two quarters. The mechanics of that sit in the revenue intelligence ROI calculator.
LinkedIn's 2026 buyer research, run with Ipsos across 900-plus B2B buyers, argues for measuring AI by deals progressed rather than activity logged. Salesforce's 2026 State of Sales, covering 4,000-plus sellers, names data quality and admin friction as the top blockers to AI returns. Both point at the same fix: clean the CRM before you expand seats, which is a CRM data strategy problem more than a tooling one.
"The additional products like forecast or engage come at an additional cost." — Scott T. Gong G2 Verified Review [2024]
One honest concession before you act on any of this. The alternatives are not equivalents. If your team is getting real value mid-contract, renegotiate rather than replace, and anchor the decision to your renewal event rather than a calendar month.
Q11. If the complaints are about scope and cost, what does a modular alternative look like? [toc=11. The Modular Alternative]
The recurring criticisms in Gong's review corpus are about scope and cost per outcome, not capability, which points toward modularity rather than replacement. Oliv AI is built as an agentic revenue layer that can sit on top of Gong rather than displace it, so a team mid-contract can add agent-run workflows without unwinding a platform that already works. Oliv AI has no public review corpus of its own, which on a page about reviews is worth stating plainly. Named customers include Sprinto and Triple Whale.
🧭 What eleven sections of review reading actually pointed at
Not accuracy. Not reliability. Not transcription quality.
Scope, cost per outcome, and rollout effort. Every recurring theme in this article traces back to one of those three. That is a shape of problem, and it has a shape of answer.
❌ Why the rip-and-replace pitch fails right now
You are reading this mid-renewal, with a quote open. A vendor telling you to migrate an entire platform is asking you to take on a second project while you are trying to close a first one.
I have made that pitch before and watched it die on the call. It deserved to. The switching cost lands on the same RevOps lead who is already carrying the rollout debt. A straight feature comparison is available in Gong versus Oliv for anyone who does want it.
✅ What changes when work is agent-run instead of app-run
First-generation revenue intelligence surfaces information and leaves the work to a person. Somebody still opens the dashboard, reads the deal board, and updates the record.
Agent-run work inverts that. The system holds context across accounts and opportunities, then executes a defined workflow against it. The person reviews output instead of assembling it. That shift is traced in more depth in the piece on AI agents versus SaaS dashboards.
That distinction is the whole argument, and it is worth being sceptical about. Plenty of vendors say agent and mean automation with a nicer label.
🧩 Where Oliv AI actually sits
Oliv AI runs agents against a continuously updated context graph of accounts and opportunities, drawing on the call and CRM data a team already has, which means it can add orchestration on top of a live Gong deployment rather than requiring a migration first. We think that posture is more useful to a reader mid-renewal than a displacement pitch, and it is checkable rather than aspirational.
Sprinto and Triple Whale use it daily. Oliv AI is SOC 2 Type II certified, GDPR and CCPA compliant, with an open export policy, and the trust documentation is public at trust.oliv.ai. The agent set itself is documented in Oliv AI agents for sales teams.
⚠️ What this page will not claim
Three disclosures, because a page about honest review reading has to hold itself to the same rule.
Oliv AI has no G2 review corpus to set against Gong's 6,694 reviews. That is a real gap, and it is not hidden here.
No price appears in this article, because the figure needs confirming before publication.
No savings number, no migration promise, and no rating. None of those are currently sourceable to a published document.
Oliv AI is also wrong for some buyers. If you want call recording alone, or you run a B2C support team, the category fit is poor and you should say so internally before anyone books a demo.
If you are sitting with a Gong quote and a usage export, that is exactly the conversation worth having. Tell us what your dormant-seat number looks like, and we will tell you honestly whether an agent layer helps. More detail on the RevOps side sits at Oliv for RevOps, and if it is useful, book a walkthrough.
FAQ's
What do Gong reviews actually say in 2026?
Gong reviews in 2026 are strongly positive across every major platform, and that consistency is the most useful thing in them.
G2: 4.7 out of 5 across roughly 6,694 reviews
TrustRadius: 9.1 out of 10 across more than 1,000 ratings
Capterra: 4.8 out of 5 across 561 reviews
Gartner Peer Insights: 4.7 out of 5 across roughly 371 identity-verified reviews
Gartner also named Gong a Leader in its 2025 Magic Quadrant for Revenue Action Orchestration. Four platforms with four different sampling methods agree, which settles the quality question and leaves fit and cost as the open ones.
The criticisms that do recur are not about accuracy, reliability, or transcription. They cluster on scope, cost per outcome, and rollout effort. We read that as feedback from people who broadly like the tool, which makes it more useful than a low-rated product's complaints, not less.
One caveat belongs in every summary. Buyers who evaluated Gong and chose something else never wrote a review, so the corpus describes users rather than the market. If you are weighing the field, the Gong alternatives guide covers what the review set structurally cannot.
Is Gong worth the price?
Gong is worth it when the platform is broadly used, and hard to justify when it is not. The honest test has three parts.
More than half your licensed users log in weekly
Managers run structured call reviews on a fixed cadence
You actively use at least two modules beyond recording
If all three hold, the price is defensible and you should renew rather than shop. If none hold, the problem is usually your seat mix rather than the vendor.
Worth stating plainly: Gong publishes no figures. Its pricing page confirms only that licences are per user and that a platform fee exists. Any per-seat dollar range you find in a comparison post is somebody's reconstruction, not a quoted price, and bringing it to a negotiation weakens your position.
Prove payback with one outcome metric held for two quarters, such as win rate or cycle-time delta. Calls recorded is activity, not return. LinkedIn's 2026 buyer research with Ipsos and Salesforce's 2026 State of Sales both point the same way, and both name data quality as the blocker. The full cost model and quote checklist sit in our Gong pricing breakdown.
What do users complain about most in Gong?
Five themes recur across verified Gong reviews, and each one needs a date check before you act on it.
Unused breadth: teams licence a platform, use recording and call review heavily, and never open the rest
Add-on cost: Forecast and Engage are separately licensed, so a platform purchase may not include the module you wanted
Setup and admin load: tracker configuration and integration work take longer than quoted
Export and data access: bulk snippet download gated behind a plan tier
Engage versus dedicated sequencers: AEs comparing it unfavourably to purpose-built tools
Accuracy and transcription quality almost never appear. That absence matters as much as the complaints.
The trap is that review sites stack five years of releases on one page, so a 2024 complaint about a module Gong has since rebuilt renders identically to one written last month. We date every quote in the body text and check each theme against Gong's current documentation before presenting it as live. Where a criticism no longer holds, we say so. The structural ones are unpacked further in our write-up on Gong limitations and challenges.
What are Gong credits and how do they change the bill?
Gong credits are a metered, company-wide pool that specific AI features draw from. Documentation from mid-2026 sets the mechanics clearly.
Roughly ten emails consume one credit
A call running over ten minutes consumes one credit
Monthly caps do not roll over, and unused credits expire
The pool is shared company-wide, not allocated per team
At zero, the API returns an error and question-based trackers stop processing new data
Consuming features include question-based AI trackers, AI Ask Anything, AI Briefer, and the MCP server. Pretrained trackers and viewing results a tracker already produced do not consume credits. Unpublishing a tracker stops its draw immediately.
This is documented metering, published openly by the vendor, and Gong has stated that existing agreements are unchanged. It is not a contract breach and should not be framed as one.
What it does change is your budgeting unit. The seat used to be the thing you forecast. Now it is the seat plus a pool whose draw depends on how many trackers your admins published, not on headcount. Tracker sprawl is far less predictable than hiring, which is why we cover the cost model separately in the Gong pricing article.
Are Gong's Smart Trackers accurate?
Yes, on detection. Gong's help documentation distinguishes keyword trackers from AI trackers and describes question-based AI trackers as detecting meaning rather than matching phrases. The widely repeated claim that Gong trackers are glorified keyword search does not survive contact with that documentation, and we have corrected our own earlier version of it.
Even the harshest reviewer in our verified sample, a 1.5-star G2 review from June 2025, called the AI highlights accurate. The complaint in that review was about a different module entirely.
The real tension is packaging, and it is checkable:
Gong Foundation advertises unlimited AI trackers
Gong's credit documentation names question-based trackers the largest credit consumer
The same documentation instructs admins to unpublish trackers that no longer provide value
Both statements are true together. Unlimited describes creation; metering governs operation.
The practical move is a quarterly audit. Export your published trackers, note who requested each, check which have been opened in ninety days, and unpublish the rest. Most teams find a third were built for a launch or a competitor scare that ended two years ago. If the goal is methodology scoring rather than theme spotting, our RevOps overview covers the agent-run alternative.
Can you export your data out of Gong?
Yes. Gong exports data, and any page claiming otherwise is contradicted by Gong's own published documentation. Repeating that myth costs you credibility in a procurement conversation.
The accurate limitations are narrower and worth knowing before you sign:
Gong's MCP server exposes three tools and returns a synthesized answer, not raw activity data. An agent querying Gong receives a conclusion, not the underlying call rows or timestamps.
Verified reviewers describe bulk snippet download gated behind a plan tier, forcing manual copying one snippet at a time.
Integration configuration takes longer than most evaluation timelines assume.
The MCP constraint matters most if you are building your own agent layer. You can consume Gong's judgment. Rebuilding that judgment elsewhere from exported rows is a different exercise.
Three things to do before signing. Run one full export during evaluation and inspect the format you actually receive. Write export format, cadence, and destination into the contract rather than an email thread. Audit recording and disclosure settings per country, because the EU AI Act disclosure duty applies from 2 August 2026 and several jurisdictions require all-party consent. Teams that do decide to move should read our guide to Gong alternatives before committing to a timeline.
Who should not buy Gong?
Gong is a strong product with consistently high ratings, so the question is fit rather than quality. Based on the recurring themes in verified reviews, four situations should give you pause.
No internal owner. TrustRadius scores support near 8.6 but implementation near 5.7. Without a named RevOps owner with blocked calendar time, the rollout stalls and the admin complaints in the review set become yours.
Small teams without a coaching cadence. The value concentrates around structured call review. If managers will not run that cadence, most of the platform goes unopened.
Teams wanting one module. If you need only sequencing or only forecasting, dedicated tools usually fit better and reviewers say so directly.
Teams that cannot answer the usage question. If you cannot pull weekly active users by role today, you cannot size the purchase honestly.
The uncomfortable inverse is also true. If more than half your users log in weekly and two or more modules are in daily use, the price is defensible and switching costs will exceed the saving. In that case, renegotiate the seat mix rather than replace. Our RevOps resource hub covers how to run that audit before the renewal call.
Enjoyed the read? Join our founder for a quick 7-minute chat — no pitch, just a real conversation on how we’re rethinking RevOps with AI.
Revenue teams love Oliv
Here’s why:
All your deal data unified (from 30+ tools and tabs).
Insights are delivered to you directly, no digging.
AI agents automate tasks for you.
Thank you! Your submission has been received!
Oops! Something went wrong while submitting the form.